Latest activity
-
TTreptower replied to the thread EFI, TPM Partitionen.Nimm "Mini Partition Wizard" damit kommt jeder klar - und damit vor dem Klicken erkennbar ist, wohin der Link führt ist er etwas länger: https://www.heise.de/download/product/minitool-partition-wizard-78907
-
TTErxleben replied to the thread SPICE client "virt-viewer" noch immer empfohlen?.Da ich nun mal einen UltraVNC-Server aktualisiert habe, mal eine Rückmeldung: Die Geschwindigkeit hat sich massiv verbessert. Jedenfalls über "Schummelverbindung" per Guacamole. Man könnte jetzt fast remote arbeiten. Allerdings funktioniert eine...
-
HHarry.Smith reacted to bishoptf's post in the thread Error when trying to remove a previously physically removed node with
 Like.
This is not a cluster, just individual nodes that have been brought into datacenter manager. I came across that command but since it wasn't a cluster wasn't sure if that was still the process. I assume that is the process for none cluster nodes also?
-
HHarry.Smith reacted to bbgeek17's post in the thread Error when trying to remove a previously physically removed node with Like.
Hi @bishoptf , Have you checked the cluster guide? https://pve.proxmox.com/pve-docs/chapter-pvecm.html#_remove_the_cluster_node Blockbridge : Ultra low latency all-NVME shared storage for Proxmox - https://www.blockbridge.com/proxmox
-
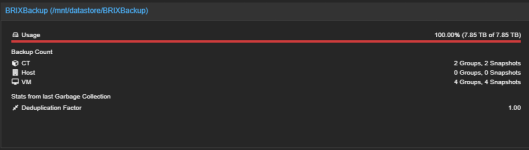
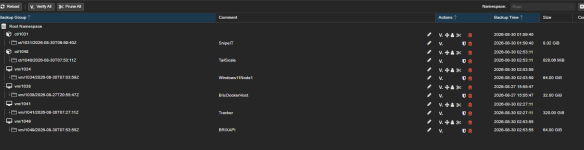
IITCowboy posted the thread No Disk Space Available (Very Confused) in Proxmox Backup: Installation and configuration.I am currently running PBS on a server with a 8tb Datastore and with 6 Vms and I am already out of disk space and I am not sure why or where the usage is. Can someone explain? See Enclosed Images
-
-
Mmorlies replied to the thread Proxmox Metrics Server - InfluxDB Cloud - Bug?.I came across same error message in my InfluxDB v3. Adding the reference to --> Bugzilla 6560 At some point, a call needs to be made here—that's something for the dev team to decide. I've taken a look at how the data was structured in InfluxDB...
-
Ssteve999 replied to the thread qcow2 file is bigger as hdd config.That 242 GiB on a 250 GiB virtual disk, with convert not shrinking anything, is the classic "allocated but never released" pattern. Discard enabled in the GUI only opens the UNMAP path from the guest to the image file - it does not free anything...
-
Jjonoliver881 reacted to r0bb10's post in the thread Proxmox Virtual Environment now available for 64-bit ARM (arm64)! with Like.
indeed the new official arm64 works! installed on stock armbian trixie and it just works! tested vm with kvm enabled, and lxc target is an s905x3 amlogic, zfs also works fine, this is actually pretty great added to my mini cluster as a spare...
-
Ggothbert replied to the thread [SOLVED] proxmox-tape barcode-label got timeout.That sounds promising, so let's go. I choose a systematic reproducible approach. *** 1 Power on the Quantum Superloader 3 (QSL3) and wait until it settles into "System Ready" state. *** 2 Power on the target host (Debian 13.7) and wait until...
-
TTErxleben replied to the thread EFI, TPM Partitionen.Es geht um das evtl. später nötige manuelle Gefrickel, beim Vergrößern von C: Umstellung passiert i.d.R. beim Update von win10 auf 11 mit zwangsläufig einher gehender SeaBios/q35 Anpassung. Beides schon auf PVE-Basis. Recovery-Partition sind eh...
-
BBu66as replied to the thread EFI, TPM Partitionen.Best Practice hab ich dafür ehrlich gesagt keine, weil die Position auf der Platte funktional egal ist. Die Firmware sucht die ESP über die Partitionstyp-GUID, nicht nach Reihenfolge. Nervig wird es eigentlich nur, wenn du hinterher C: vergrößern...
-
 UdoB reacted to SteveITS's post in the thread [SOLVED] Issues with New Install, loosing access to VMs with Like.
My first thought is you’re overcomplicating Ceph. Why not one pool with lots of drives for resilience and more distributed I/O? What does the top of the Ceph status page show when one host is off? Should not be worse than yellow.
-
JJohannes S reacted to Bu66as's post in the thread Seit Update auf Proxmox 9.2 Backup und Replication sehr träge with Like.
Dass pvestatd hängt, ist entscheidend. Der Daemon klappert der Reihe nach alle konfigurierten Storages ab, und wenn eines davon zäh ist oder gar nicht antwortet, bleibt er genau da stehen. Dann wird der Node im Cluster grau, Tasks rennen in...
-
JHi, All of these are end-of-life, best to use the latest ISO available for new installations and keeping your system up to date. Why should the ISO file be required to start the Proxmox Backup Server? Or are you running it as VM and the VM...
-
JJohannes S reacted to fabian's post in the thread Kernel 6.17 - End of Support after July with Like.
there are no more security or other upgrades for it. given the rate of (often exploitable) issues in the kernel, running an unsupported kernel is not a good idea on any kind of production system..
-
Ddmpm replied to the thread [SOLVED] Node crashes when trying to update to proxmox-kernel-7.0.14-19.The first time it happened it just locked up permanently and I had to do a hard reboot but after that the node just became unavailable in the UI or via SSH temporarily and then recovered itself. It wasn't rebooting so I think the power spike when...
-
Ffti-fred replied to the thread kvm: Desc next is 2.We are at 4 days without a recurrence. If there are more issues I'll go to v204 or v302.
-
Ddmpm reacted to Impact's post in the thread [SOLVED] Node crashes when trying to update to proxmox-kernel-7.0.14-19 with Like.
Please check with a connected monitor as well. Does it just reboot, power off, freeze or what happens exactly?
-
JDanke für deinen Klaps auf den Hinterkopf. pagefile hat hier tatsächlich irgendein Künstler deaktiviert.
-
THat jemand vielleicht ein Bestpractice auf Tasche, mit dem ich die o.g. Partitionen von umgestellten WinVMs am liebsten automatisiert an den Anfang verschieben kann?