LXC Boot and vzdump Failures on Ceph RBD after Upgrade: fsconfig() failed ... Can't lookup blockdev (Exit Code 32)

chrispage1

Well-Known Member
Sep 1, 2021
110
54
48
34
Hi,

After all of the CVE's and security disclosures over the past week or two, I thought it'd be useful to upgrade my Proxmox nodes to the latest. I recently updated everything to PVE 9 & Ceph 19 and it has been working without fault for a few weeks. Since todays package updates, I am getting sporadic LXC boot and vzdump failures with the error Can't lookup blockdev (Exit code 32)

Environment:

- PVE 9.1.9 / Linux 6.17.13-9-pve (2026-05-15T08:46Z)
- Ceph 19.2.3 - RBD (krbd mapped)
- Guest LXC container 119

---

After upgrading a cluster node, I hit two distinct but identically rooted issues involving LXC container storage mapping. The system fails during automated storage operations with a mount exit code 32, specifically spitting out an underlying kernel fsconfig() error.

I suspected it could be just the one node because it was ahead of the others so proceeded to continue the upgrade and can replicate the issue on more than one node now.

Symptom 1: Container Fails to Start (HA or Local)​

When attempting to boot the container, it immediately crashes during the pre-start phase. Checking the container debug logs (lxc-start -n 119 -F -l DEBUG -o /tmp/lxc.log) gave:

Code:
lxc-start produced output: mount: /var/lib/lxc/.pve-staged-mounts/mp0: fsconfig() failed: /dev/rbd-pve/[FSID]/ceph_data/vm-119-disk-1: Can't lookup blockdev.
dmesg(1) may have more information after failed mount system call.
command 'mount /dev/rbd-pve/[FSID]/ceph_data/vm-119-disk-1 /var/lib/lxc/.pve-staged-mounts/mp0' failed: exit code 32
ERROR: Failed to run lxc.hook.pre-start for container "119"

Manually running rbd map to force the symlink to generate, leaving it mapped, and then executing pct start allowed the container to boot on a subsequent attempt.

Symptom 2: vzdump Snapshot Backups Fail​

Even with the container successfully running, executing an automated vzdump backup in snapshot mode to a Proxmox Backup Server (PBS) fails instantly at the mount phase:

Code:
INFO: create storage snapshot 'vzdump'
Creating snap: 100% complete...done.
/dev/rbd4
mount: /mnt/vzsnap0: fsconfig() failed: /dev/rbd-pve/[FSID]/ceph_data/vm-119-disk-0@vzdump: Can't lookup blockdev.
umount: /mnt/vzsnap0/: not mounted.
ERROR: Backup of VM 119 failed - command 'mount -o ro,noload /dev/rbd-pve/[FSID]/ceph_data/vm-119-disk-0@vzdump /mnt/vzsnap0//' failed: exit code 32

With some consultation with AI, it appears to be an asynchronous race condition between the kernel mapping the RBD and udevd generating the links inside /dev/rbd-pve/[FSID]/...

Is this a known issue or has anyone else experienced this?
 
i did try to reproduce but couldn't, more information about your setup (ct/ceph config etc.) would be useful.

does this persist after you reboot your nodes?
 
Hi Dominik,

Thanks for your reply!

Sure - happy to supply as much information as I can. So this has only begun since the latest update and reboot and can be replicated across nodes.

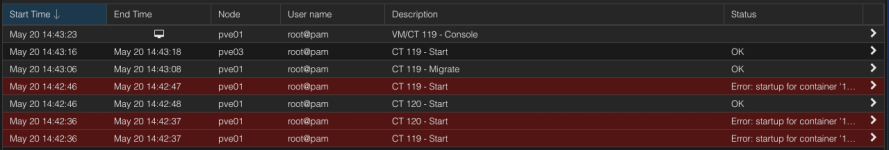
This cluster has gone all the way from PVE 6 with Ceph 16 (from memory) and been upgraded up to PVE 9 with Ceph 19. The issues seem spontaneous, like some sort of race condition. I can replicate with multiple containers

1779284761517.png

Here are the exact upgrade version changes from my dist-upgrade log:
  • Proxmox Kernel: upgraded to proxmox-kernel-6.17.13-9-pve-signed (6.17.13-9)
  • pve-container: upgraded from 6.1.4 to 6.1.5
  • udev / systemd: upgraded from 257.9-1~deb13u1 to 257.13-1~deb13u1
  • libc6: upgraded from 2.41-12+deb13u2 to 2.41-12+deb13u3

Here is my entire LXC config (some bits redacted):

Code:
root@pve03:/etc/pve/lxc# cat 119.conf
arch: amd64
cores: 6
features: nesting=1
hostname: search-server
memory: 10240
mp0: ceph_data:vm-119-disk-1,mp=/etc/meilisearch,backup=1,size=20G
nameserver: 8.8.8.8 8.8.4.4
net0: name=eth0,bridge=BRIDGE,firewall=1,gw=XXX.XX.XXX.XXX,hwaddr=02:61:D4:8F:94:07,ip=XXX.XX.XXX.XXX/27,type=veth
ostype: ubuntu
rootfs: ceph_data:vm-119-disk-0,size=20G
swap: 0
tags: services
unprivileged: 1
 
Last edited:
Possibly related observation from our environment.

Same symptom: mount: ... fsconfig() failed: /dev/rbd-pve/[FSID]/[pool]/[image]@vzdump: Can't lookup blockdev during vzdump --mode snapshot of LXC on Ceph RBD. Persists across systemctl restart systemd-udevd and reboot.

Versions:
- pve-manager 9.1.19, pve-container 6.1.10, ceph-common 19.2.3-pve4
- Running kernel: proxmox-kernel-7.0.2-6-pve (same symptom on this kernel as OP saw on 6.17.x)

Tests point to a NUMA-related trigger:

In a 7-node cluster running identical software stack, our tests show the bug triggers reliably only on the single dual-socket / dual-NUMA-node host. All 6 single-socket hosts appear unaffected. Migrating the failing CT to a single-socket host and running vzdump there:
works. Migrating back: failure resumes.

Tests also suggest it's the timing race described:
- After vzdump's mount fails, the expected symlink /dev/rbd-pve/[FSID]/[pool]/[image]@vzdump exists and points correctly to the mapped /dev/rbdN
- Running the same mount -o ro,noload manually after the failure succeeds
- ceph-rbdnamer-pve returns the correct path when invoked manually on the still-mapped snap device

Tentative hypothesis (not verified):
On dual-socket NUMA systems, cross-socket scheduling between the kernel RBD-map event path and the systemd-udevd worker running ceph-rbdnamer-pve may extend symlink-creation latency past vzdump's mount syscall. On single-socket hosts the worker tends to stay colocated
and wins the race.
 
I'm still struggling with issues having updated to 9.2.2 from 9.1.9

TASK ERROR: unable to create CT 135 - command 'mkfs.ext4 -O mmp -E 'root_owner=100000:100000' /dev/rbd-pve/24f246db-267a-4a95-9346-2142944edec8/ceph_data/vm-135-disk-0' failed: exit code 1
 
We hit the same error today and found the cause on our side: a second systemd-udevd left over from the initramfs. Killing it fixed the problem right away. Maybe worth checking on the affected hosts in this thread:

Code:
ps -eo pid,cgroup,args | grep [u]devd

Normal is one line in system.slice/systemd-udevd.service. On our broken node there was a second one:

Code:
  276 0::/init.scope                               /usr/lib/systemd/systemd-udevd --daemon --resolve-names=never
  935 0::/system.slice/systemd-udevd.service/udev  /usr/lib/systemd/systemd-udevd

PID 276 is the udevd started by initramfs-tools (scripts/init-top/udev). It should be stopped by udevadm control --exit in scripts/init-bottom/udev, but it kept running since boot (5 days). Its binary and its rules directory were already deleted with the initramfs, so it processes every uevent with no rules at all and sends the "processed" udev event within about 0.2 ms. rbd map waits for the udev event, gets this early one and returns. The real udevd creates the /dev/rbd-pve/... link about 10 to 13 ms later. vzdump (or the container start) mounts in between and gets "Can't lookup blockdev", exit code 32.

Setup
3 node PVE cluster with hyperconverged Ceph, all nodes on the same versions:
Code:
pve-manager: 9.2.20
kernel: 6.17.13-21-pve (pinned)
pve-container: 6.1.14
libpve-storage-perl: 9.1.10
lxc-pve: 7.0.0-2
ceph: 19.2.6-pve4
udev / systemd: 257.13-1~deb13u1
initramfs-tools: 0.148.4
zfs-initramfs: 2.4.4-pve1
root on ZFS (boot=zfs), UEFI, proxmox-boot-tool
RBD storage has krbd 0, so only containers use krbd. No custom udev rules and no custom initramfs hooks or scripts.

What failed
vzdump snapshot mode of a small LXC (2 GiB ext4 rootfs on RBD), twice in a row:
Code:
mount -o ro,noload /dev/rbd-pve/<fsid>/<pool>/vm-128-disk-0@vzdump /mnt/vzsnap0//
fsconfig() failed: ... Can't lookup blockdev
exit code 32
The failed job leaves the @vzdump snapshot mapped and parent: vzdump in the CT config. Cleanup: rbd unmap /dev/rbdN for the snapshot device, then pct delsnapshot <vmid> vzdump.

How we narrowed it down
Test without vzdump: a throwaway 64 MiB image with one snapshot, 30 rounds of rbd map pool/img@snap, then right away test -e /dev/rbd-pve/... and mount -o ro,noload, then unmap. Same script on all three nodes:
Code:
                     link there when map returns   immediate mount   map median
node 1 (broken)      0/30                          30/30 failed      28.5 ms
node 2               30/30                         30/30 ok          41.6 ms
node 3               30/30                         30/30 ok          37.9 ms
node 1 after fix     30/30                         30/30 ok          ~43 ms
Node 1 and node 2 have the same CPU (i7-14700, single socket, one NUMA node), so it was not the CPU or NUMA.

udevadm monitor --kernel --udev --property on node 1 showed every block event twice from udev. The first one came about 0.2 ms after the kernel event without DEVLINKS. The second one came about 13 ms later with DEVLINKS, including the rbd-pve link. The two had different USEC_INITIALIZED values. On the other nodes each event came only once.

Fix
kill -TERM 276 (it stopped within a second). The normal udevd was not touched. After that the 30 round test passed 30/30 and the container backup worked.

What we do not know
Why udevadm control --exit did not stop it. The journal does not cover the initramfs stage and dmesg shows nothing unusual. The other two nodes booted in the same rolling update with the same packages and did not keep a second udevd, so it looks timing dependent. That would also explain why a reboot helps for some people and not for others.

Suggestion: map_volume in PVE/Storage/RBDPlugin.pm returns the /dev/rbd-pve/... path right after rbd map without checking that it exists. A short wait for the link there would make PVE robust against this.

Code:
STARTED: boot time (same second as the kernel), PPID 1, cgroup 0::/init.scope, 1 thread
/proc/276/exe -> /usr/bin/udevadm (deleted)      same md5 as the installed udevadm
/proc/276/root and mount namespace: same as PID 1, it still sees the old initramfs rootfs
  (conf dev etc kernel proc root run scripts sys tmp), usr/lib/udev/rules.d/ is empty
environment: initramfs init variables (ROOT=ZFS=rpool/ROOT/pve-1, BOOT=zfs, rootmnt=/root, init=/sbin/init)
sockets: kernel uevent netlink (groups 1), and it was still listening on /run/udev/control
  next to the socket of the real udevd (the one held by systemd)

Code:
KERNEL[429479.675749] add      /devices/rbd/9/block/rbd9 (block)   SEQNUM=14772
UDEV  [429479.675931] add      /devices/rbd/9/block/rbd9 (block)   SEQNUM=14772 USEC_INITIALIZED=429479675757  (no DEVLINKS)
UDEV  [429479.688811] add      /devices/rbd/9/block/rbd9 (block)   SEQNUM=14772 USEC_INITIALIZED=429479675752
  DEVLINKS=/dev/rbd/<pool>/racetest-udev@t /dev/disk/by-diskseq/107 /dev/disk/by-uuid/... /dev/rbd-pve/<fsid>/<pool>/racetest-udev@t
After killing PID 276 there is only one UDEV line per event and the link exists when rbd map returns.

rbd map opens a NETLINK_KOBJECT_UEVENT socket bound to nl_groups=0x2 (udev processed events), receives 3 udev events and exits. Under strace the map took 66 ms and the link was already there, so anything that slows down the map hides the problem.

Code:
21:00:01.222019 kernel: rbd: rbd9: capacity 2147483648 features 0x3d
21:00:01.240058 ERROR: Backup of VM 128 failed ... exit code 32
21:16:57.945007 kernel: rbd: rbd9: capacity 2147483648 features 0x3d
21:16:57.962737 ERROR: Backup of VM 128 failed ... exit code 32
On the working nodes there were 97 to 160 ms between the kernel map message and the successful mount.

Happy to share the test scripts or run more checks if that helps.