

After updating a non-production Proxmox VE node, the host hangs at boot right after:
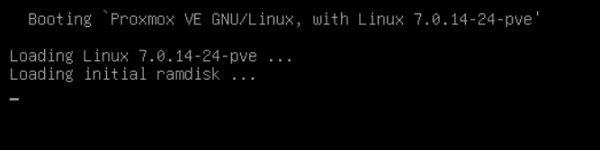
There is no further output, even after waiting several minutes [confirm wait time: ___ min].
Environment
Cmdline that hangs on the 7.0 kernels
hugepages=499712 × 2 MiB = 999,424 MiB (~976 GiB), which leaves about 32 GiB for the host.
What I tested
My suspicion
Since 6.17.13-21 boots with the same cmdline and RAM, I suspect a regression or behavior change in boot-time hugepage allocation in the 7.0 series. It could also be extreme slowness allocating ~500k 2M pages that early in boot, but I haven’t been able to confirm that yet.
Questions
I can provide dmesg, journalctl -b, numactl -H, /proc/meminfo and the /boot/config-* settings if needed.
Bash:
Loading Linux 7.0.14-24-pve ...
Loading initial ramdisk ...
There is no further output, even after waiting several minutes [confirm wait time: ___ min].
Environment
- Hardware: Dell [model], BIOS [version], Intel CPU [model], [1 or 2] sockets
- RAM: 1,031,426 MiB total (~1007 GiB)
- Proxmox VE: pve-manager 9.2.21
- Failing kernels: 7.0.14-24-pve and 7.0.14-25-pve
- Working kernel: 6.17.13-21-pve
- Root on LVM (/dev/mapper/pve-root), booting with GRUB
- All VMs on this host use hugepages (no non-hugepage VMs)
Cmdline that hangs on the 7.0 kernels
Bash:
GRUB_CMDLINE_LINUX_DEFAULT="quiet intel_iommu=on default_hugepagesz=2M hugepagesz=2M hugepages=499712"hugepages=499712 × 2 MiB = 999,424 MiB (~976 GiB), which leaves about 32 GiB for the host.
What I tested
- Kernel 6.17.13-21-pve with the same cmdline (IOMMU + hugepages=499712): boots normally [confirm HugePages_Total = 499712].
- Kernels 7.0.14-24-pve and 7.0.14-25-pve with the same cmdline: both hang after “Loading initial ramdisk”.
- Kernel 7.0.14-25-pve without intel_iommu=on and without the hugepages parameters: boots.
- Kernel 7.0.14-25-pve with intel_iommu=on only: boots. dmesg shows DMAR: IOMMU enabled and 287 entries under /sys/kernel/iommu_groups/, so IOMMU itself looks fine.
- Pending: [result with hugetlb_free_vmemmap=on] / [result with hugepages=450000] / [result with loglevel=7 earlyprintk=vga,keep or Serial Over LAN].
My suspicion
Since 6.17.13-21 boots with the same cmdline and RAM, I suspect a regression or behavior change in boot-time hugepage allocation in the 7.0 series. It could also be extreme slowness allocating ~500k 2M pages that early in boot, but I haven’t been able to confirm that yet.
Questions
- Is there any known change in the 7.0 series (hugetlb, vmemmap, struct page init) affecting cmdline hugepage reservation on hosts with ~1 TB of RAM?
- Is allocating via vm.nr_hugepages in /etc/sysctl.d/ (after boot) the recommended approach in this scenario?
- Is there a recommended cmdline parameter for the 7.0 series in this case?
I can provide dmesg, journalctl -b, numactl -H, /proc/meminfo and the /boot/config-* settings if needed.
