

You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.
Same issue here, and I think I found what fixed it in my case.
Setup: PBS 4.2.8 (kernel 7.0.14-25-pve), S3 datastore on Hetzner Object Storage (hel1), vhost-style addressing, provider quirk `skip-if-none-match-header` already set. Syncs to the S3 datastore were fine the whole time, only GC was failing.
Symptoms:
- GC phase 1 always completes, phase 2 fails after 1 to 17 minutes with `error reading a body from connection: unexpected EOF during chunk size line`
- first failures end of September, then failing every single night from early October (19 nights in a row)
- one night it failed with `unexpected status code 405 Method Not Allowed` instead
What did NOT fix it:
- moving GC to its own time slot
- `--limit-passive-requests 10 --limit-active-requests 10` on the endpoint (GC lasted longer, then failed the same way)
What fixed it: the `delete-objects-via-delete-object` provider quirk, which makes PBS delete objects one by one instead of using the batch `DeleteObjects` call. The 405 was the hint. Note that `--provider-quirks` replaces the whole list, so pass the existing quirks again:
```
proxmox-backup-manager s3 endpoint update <endpoint-id> \
--provider-quirks skip-if-none-match-header \
--provider-quirks delete-objects-via-delete-object
```
The next manual GC completed in 9m20s (3 GiB removed), and the scheduled run the following night was also OK.
So in my case the truncated body seems to come from the batch delete response rather than from the ListObjectsV2 listing. I still have the request limits in place and will remove them later to check whether they play any role; I'll report back.

I'll test that, because my jobs are meanwhile failing since almost 2 weeks consecutively. GC is already currently running. I'll report back for my 2 instances, if this solved the problem. If this is confirmed to work, this might be worth reporting back to hetzner because they keep how2s for usage of s3-buckets in various scenarios.
Last edited:
One of my instances already finished. it actually took 3 attempts, because of
I'll now test my other instance, however, this one will take much longer, because it has much more content to manage.
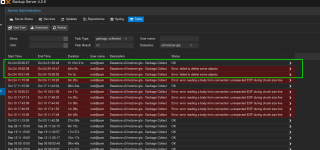
failed to delete some objects (without further details) in step 2. However, I think the api-command to actually delete the object went through just fine anyways, because on subsequent tries the GC ran longer until it eventually finished (see screenshot). so far this looks good, if the new errors were ultimately just an arftifact of the failed runs before (I hope so), then this might indeed the solution, but we'll see. I'll now test my other instance, however, this one will take much longer, because it has much more content to manage.
Update after a few more days, confirming what zeus86 saw.
The `delete-objects-via-delete-object` quirk got rid of the `unexpected EOF` errors, but GC is still not reliable: as soon as there is a meaningful amount of garbage (a few thousand chunks), phase 2 fails with `failed to delete some objects`. It took 4 attempts on 25/10 and 5 attempts on 26/10 to get a green run.
The deletes do go through between failures. Watching the object count in the Hetzner console, it drops in steps of 500 objects (122,336 → 121,836, then 124,393 → 121,893), then the task aborts. Each retry finishes part of the job, and the last one completes in under a minute.
I also got a `504 Gateway Timeout` on a chunk upload during a sync on 25/10. Together with the truncated bodies, the 405 I saw on 09/10 and the failed deletes, this looks like instability on Hetzner's side (hel1 here), which PBS makes visible because it doesn't retry. I've opened a ticket with Hetzner and will report back.
On the PBS side, two things would help a lot:
- log the object key and the S3 error code for each failed delete (right now the task log only says `failed to delete some objects`);
- retry transient errors (5xx, truncated bodies) instead of aborting the whole GC.
Current workaround: rerun GC until it's green. No data loss, only garbage kept a little longer.
Setup for reference: PBS 4.2.8, Hetzner hel1, quirks `skip-if-none-match-header` + `delete-objects-via-delete-object`, `--limit-active-requests 10 --limit-passive-requests 10`, GC scheduled alone at 04:00 UTC.
meanwhile the second instance finally also went through. as it can be seen from the screenshot, this instance had failure for longer in the past in total. once in a while a run finished fine (after putting in to a timeslot where nothing else was happening and rate-limiting api-requests), but ultimatively nothing changed fundamentally. after applying the provider-quirks as suggested it took 3 more attempts with
so, so far, the quirks seem indeed to be the solution, ideally someone would let confirm this by hetzner themselves (i assume they at least should know what their S3-infrastructure is expecting from a client...).
by the way: both quirks can also be set via gui in the "
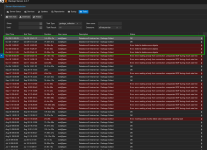
failed to delete some objects, but after that, 2 runs subsequently succeeded (the second one only took that long, because there was also a verify-job running, and the hardware is kinda slow and dated).so, so far, the quirks seem indeed to be the solution, ideally someone would let confirm this by hetzner themselves (i assume they at least should know what their S3-infrastructure is expecting from a client...).
by the way: both quirks can also be set via gui in the "
s3-endpoints" tab in the respective entry.