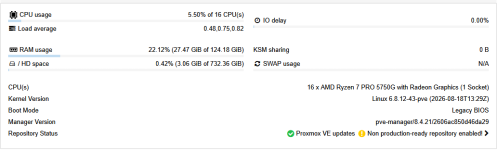
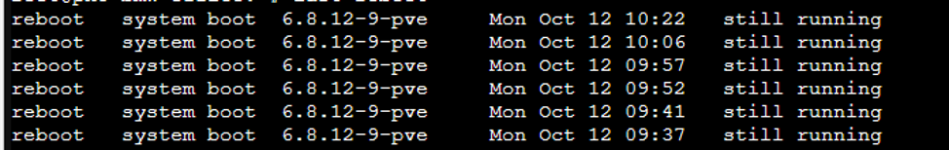
Well...
That file gets saved as "px3_diagnostics_summary.zip" - which is a lie not the case. Inside of it there is a *.rar archive. I stopped there.
But then my curiosity won. I installed an appropriate software package - exclusively to be able to read that file and (possibly) to help you.
After extraction I found... a file named "px3_diagnostics_summary.docx". And I have no tooling for that kind of stuff readily available on this machine - and I won't install LibreOffice only to read your report.
Sorry, I'm out...
px3-office — Summary of Reboot Diagnostics
Investigation materials as of 20.10.2026. Main series of load tests: 15–19.10.2026. Log timestamps are UTC+3. The configuration and PCIe topology below refer to the system prior to the motherboard replacement on 20.10.2026, unless otherwise stated.
1. Manifestation of the Fault
The node periodically reboots without a logged orderly OS shutdown. Initially, a correlation was found between reboots and incoming replication of CT 104. Later, the fault was reproduced without pvesr: with a local zfs send | zfs receive from the NVMe pool to the SATA pool concurrently with incoming iperf3 TCP traffic.
In the available logs, there is no panic, Oops, MCE, or SATA timeout immediately before the investigated failures. After boot, the pools returned to ONLINE, and the READ/WRITE/CKSUM counters in the checks shown were zero.
The fault does not occur on every run. Operations of the same type completed successfully in some cases. State was not recorded separately.
2. Configuration (prior to motherboard replacement)
| Component | Parameters |
| Proxmox | Branch PVE 8.4; in the original configuration pve-manager 8.4.19 |
| Kernel px3 | 6.8.12-9-pve, after update — 6.8.12-43-pve |
| OpenZFS px3 | 2.2.7-pve2, after update — 2.2.10-pve1 |
| Kernel px5 | During comparative testing — 6.8.12-9-pve |
| Boot | Legacy BIOS, GRUB, root file system on ZFS |
| Pool ssd | Mirror of 2× Samsung 870 QVO 4 TB, firmware SVQ02B6Q, AMD AHCI |
| Management px3 | 192.168.77.40/24, enp4s0f0 → vmbr0 |
| Replication and Corosync px3 | 172.20.20.3/24, enp4s0f1 → vmbr1 → vmbr1.200, VLAN 200 |
| Addresses px5 | Management 192.168.77.9; data 172.20.20.5 |
Both network ports used on px3 belong to a single BCM5720. Checking via management and data changed the port and network route, but not the adapter model or driver.
3. Changes and Preliminary Checks
| Action | Result / data limitation |
| BIOS update and installation of amd64-microcode | Reboots continued |
| Power-supply replacement | Issue persisted |
| CPU stress test | Conducted as noted in the report; program, parameters, and detailed results not saved |
| MemTest of mixed ECC/non-ECC kit | According to the report, the test did not pass |
| Separate verification of memory kits | No errors found; this does not confirm the correctness of all subsequent memory configurations |
| Kernel and OpenZFS update | Failure persisted |
4. Online Testing
The following snapshot was used:
text
ssd/subvol-104-disk-0@diag-px3-20261016-base
Full stream — about 65.3 billion bytes, or 60.8 GiB. The resulting copy, when compressed, occupied about 28.2 GiB. Separate diagnostic datasets were created for manual receive tests; the working CT 104 dataset was not used as their recipient.
| Test | Result |
| Only iperf3: 400, 560, 720, 880, 930 Mb/s | Short tests completed without resets or TCP retransmits. Separate longer runs at 720 Mb/s also worked |
| fio-3.33, sequential 128 KiB write to SATA | Short tests without reset. Used ioengine=sync, direct=0, end_fsync=1. Multi-second delays were observed |
| Short fio run together with iperf3 | Successful |
| Full zfs send → SSH → /dev/null on px3 | Successful |
| Local full receive in NVMe rpool | Successful |
| Full remote receive in NVMe on the new kernel | Successful via management and data. In alternating… The statement "NVMe never failed" does not match the results |
Checking Replication Launch Methods
Used:
bash
pvesr run --id 104-1 --verbose
pvesr schedule-now 104-1
On the new kernel, the transfer of about 4.62 GiB with rate=200 and the transfer of about 1.62 GiB without the rate parameter completed successfully. After testing, rate=50 was restored.
The difference between direct launch and launch via the scheduler was not identified as the cause of the failure. The failure was reproduced even without pvesr.
5. Concise Commands of Performed Tests
The commands are provided to document the methodology. In the tests, tmux, separate dataset names, set -o pipefail, logging of output, and exit-code checking were used. zfs receive -F was not applied. SSH parameters for host-key verification are omitted below.
Remote Receive on SATA
On px5:
bash
zfs send -Pv ssd/subvol-104-disk-0@diag-px3-20261016-base |
ssh -T
root@172.20.20.3 \
'zfs receive -u -o mountpoint=none -o canmount=off'
netconsole via the Management Network
text
/var/lib/px3-crash/netconsole/kernel.log
On the px3 system, /root/px3-io-watch.py was created. Every second it collected CPU usage, I/O wait, MemAvailable, RX on two interfaces, completed writes and their average latency, outstanding I/O, dmu_tx counters, and the last completed TXG. Lines prefixed with PX3_IO_DIAG were sent through /dev/kmsg to netconsole.
Failure 19 Oct 2026, 14:24
| Time | Observed |
| 14:24:09 | Data-interface RX 774 Mbit/s, write to Samsung 131/132 MB/s |
| 14:24:10 | RX drops to 59 Mbit/s; at 14:24:10.949 the neighboring node records a Corosync link down |
| 14:24:11–19 | Data-interface RX 0; monitor keeps running, messages arrive via management, both Samsungs continue completing writes |
| 14:24:19 | Last measurement: write 39/42 MB/s, awaitW 0.7/28.1 ms, inflight 0/10, MemAvailable 118.6 GiB |
| 14:24:40 | Start of a new boot according to uptime -s |
| 14:25:05–06 | Node returns to Corosync |
The metrics refer to completed operations, not the age of pending requests. The TXG sync value refers to the last completed transaction group, not the current wait time. These metrics do not establish the cause of the reset.
6. Kdump, Watchdog and Crash Logs
Configured:
text
crashkernel=1G
kernel.nmi_watchdog=1
kernel.softlockup_panic=1
kernel.hardlockup_panic=1
kernel.panic=60
softdog: soft_panic=1
Before the load tests, the following were checked:
bash
cat /sys/kernel/kexec_crash_loaded
kdump-config status
systemctl is-active px3-netconsole.service
Returned 1, ready to kdump, and active. Kdump is configured to send via SSH to px6. The watchdog-mux was running; in one of the checks the local HA LRM was idle.
A full vmcore from real failures was not obtained. In the shown file lists, only dmesg.202610141437 of size 97 682 bytes was present. Successful saving of a full crash dump has not been confirmed.
The absence of a dump does not establish hardware cause. The loads were zero. Network error/drop counters after reboot were also zero. The moment of setting PCIe flags and their relation to failures was not recorded.
On several boots there was TSC unstable relative to HPET; the clocksource hpet was used. The warning persisted after the BIOS update. Its connection to the reboots has not been established.
7. Latest Confirmed State and Diagnostic Data
During the completion of the test series:
- 104-0: replication px5 → px2 was temporarily disabled, then re-enabled and completed successfully.
- 104-1: replication px5 → px3 enabled, returned rate=50 MB/s.
- The quota rpool/diag-recv was increased from 128 to 200 GiB for additional copies.
- On px6 the incident directory /var/lib/px3-crash/incident-20261019-142524/ was saved with a copy of kernel.log.
Created rpool/diag-recv/*, ssd/diag-write-test, ssd/diag-local-recv, as well as datasets named ssd/diag-remote-recv*, ssd/diag-mgmt-recv and others.
8. Conclusions
Based on the available data, it was not possible to identify the specific faulty component and the reboot mechanism. Replacing the motherboard and power supply, updating BIOS, microcode, kernel, and OpenZFS did not resolve the problem.
There are no results of testing via Intel I211, moving the Samsung to another SATA controller, CPU replacement, tests in SystemRescue or other independent boot environments in the materials. The model of the new motherboard and the final memory configuration need clarification.