pve-qemu-kvm 11.0.3-4 performance degradation

atomek

Member
Nov 19, 2023
9
0
6
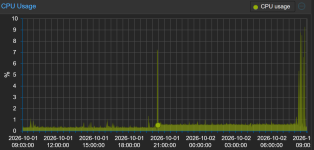
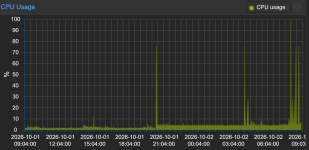
I'm doing frequent proxmox updates, today I've noticed much higher CPU usage of VMs (linux and BSD) after yesterday upgrade. I've checked that kernel was updated to 7.0.14-20-pve, but reverting the issue remains. After I downgraded pve-qemu-kvm 11.0.3-4 to pve-qemu-kvm 11.0.3-3 the issue is gone. Have you noticed this? Can I report it somewhere?


1790924600232.png

1790924629344.png

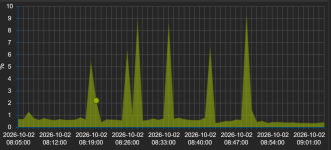
And this is after the downgrade of package - notice the idle CPU usage at around 8:50 dropped in half:


1790924700210.png
 
Hi,
the only changes in the pve-qemu-kvm package were in very specific subsystems related to backup, snapshot and migration and should not affect performance otherwise:
Code:
pve-qemu-kvm (11.0.3-4) trixie; urgency=medium

  * vma: reject archive member names that are not a single path component
    when reading an archive. Previously, extracting a crafted backup archive,
    as done on restore, could write configuration files outside of the
    extraction directory.

  * vma: fix out-of-bounds reads and resulting crashes when reading an
    archive with a crafted header, for example one containing a zero-length
    name or an invalid blob buffer location.

  * savevm-async: fix leaking the state file channel and a reference to its
    block backend each time the VM state is saved or loaded, for example for
    snapshots including RAM or for hibernation.

  * migration: fail with an error instead of possibly crashing when the
    Proxmox Backup Server dirty bitmap state in an incoming migration stream
    or saved VM state is corrupt.

 -- Proxmox Support Team <support@proxmox.com>  Wed, 30 Sep 2026 22:53:48 +0200

Are you sure nothing else changed between the tests? Can you check the timings of the latest boots and which kernel each used?
 
Hello,

I am seeing similar behaviour on a Debian Linux VM running Checkmk in my Proxmox cluster.

Current package versions:
- pve-manager: 9.2.21
- qemu-server: 9.2.10
- pve-qemu-kvm: 11.0.3-4
- Kernel: 7.0.14-20-pve

On October 1, I updated the nodes and performed rolling reboots with HA live migrations. On hv06, the upgrade from pve-qemu-kvm 11.0.3-3 to 11.0.3-4 was logged at 06:57:18. VM 100 was subsequently migrated from hv04 to hv06, completing the VM-state transfer at 07:45:27, and back to hv04 at 07:58:37.

The monitoring history shows a sustained increase in the VM's baseline load that morning. CPU usage reported from inside the guest was substantially lower than the host-side VM CPU usage. A subsequent VM restart did not provide a lasting improvement. Moving the VM to hv06 changed the pattern to frequent CPU spikes, but did not eliminate the issue.

Today I downgraded only pve-qemu-kvm on hv06 to 11.0.3-3, retaining kernel 7.0.14-20-pve. The running VM process now reports:
QEMU emulator version 11.0.3 (pve-qemu-kvm_11.0.3-3)

The initial result is encouraging: the frequent spikes have disappeared so far, and host-side VM CPU usage has settled around 9–11%. However, this is still preliminary; I am allowing at least an hour for Checkmk to catch up after startup before drawing a conclusion.

One important caveat: automatic service restarts during the downgrade included pve-cluster and both HA services, followed by an unexpected host reset, apparently due to fencing. Consequently, this comparison includes both a host and a guest restart, rather than solely a QEMU package change.

ChatGPT assisted me with researching this thread, reviewing the monitoring screenshots and migration logs, and drafting this comment. The commands were executed by me, and the observations above are from my own system.

Thank you for investigating. I can provide the graphs and migration logs if useful.
 
  • Like
Reactions: mcmxcviiii
Are you sure nothing else changed between the tests? Can you check the timings of the latest boots and which kernel each used?

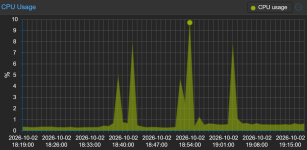
I confirm there is something wrong. I've retested this in isolation, only changing pve-qemu-kvm package: (11.0.3-4, 11.0.3-3). The stats are from Debian 13 VM (latest updates)

18:10: booted with 11.0.3-3, after startup spike the load stabilise at 0.26-0.3 %
18:50: booted with 11.0.3-4, after startup spike the load stabilise at 0.6-0.7 % - one reboot of VM to see if change anything, but idle stays elevated


1790961499830.png


I've asked The Wise (GPT) what could go awry with commits for 11.0.3-4, here is what she told me (sounds crypto to me but maybe you can find it useful):

The interesting commit: 513917f9a7
This commit fixes this lifetime sequence:
qio_channel_savevm_async_new()
│
▼
QIOChannel
│
├── owns BlockBackend ref
│
▼
qemu_file_new_input/output()
│
└── takes its own QIOChannel reference

Previously, Proxmox retained the original channel reference in addition to the one owned by QEMUFile. As a consequence, after closing the QEMUFile, the QIOChannel and its BlockBackend reference could remain leaked.
-4 effectively does:
QIOChannel *ioc = qio_channel_savevm_async_new(...);

f = qemu_file_new_...(ioc);

/* QEMUFile now owns its reference */
object_unref(ioc);

Proxmox's patch discussion explicitly describes this as a QIOChannel/BlockBackend leak occurring for snapshots/state loading. Lore Proxmox
There are two reasons I don't think this explains ordinary idle CPU:
1. It isn't executed continuously. It belongs to savevm-async, used when saving/loading VM state—RAM snapshots, hibernation, rollback/state load, etc.
2. Its expected effect is to remove a leaked object, not add a polling object or worker. If anything, after a state operation it should leave fewer resources around.
A refcount bug could theoretically cause unexpected lifecycle behavior, which is why this is the first commit I'd bisect if the package is conclusively responsible. But the usual manifestation would be a crash, use-after-free, failed snapshot, or state-operation problem—not every idle VM consistently consuming twice as much CPU.

The other QEMU-process changes
45d5a170a7 changes:
f->buf = malloc(buffer_size);
...
free(f->buf);

to:
f->buf = g_malloc(buffer_size);
...
g_free(f->buf);

For savevm-async the buffer is 4 MiB. The significant semantic difference is OOM behavior: g_malloc() does not return NULL in the ordinary way. There is no timer, poll, coroutine wakeup, thread creation, or repeated allocation introduced by this change. Mail Archive
b6f2adbcea affects pbs_state_load(): zero-sized state returns early, allocation uses g_try_malloc(), errors are handled instead of potentially dereferencing NULL, and the buffer is automatically freed. Again, this only matters while loading migration/saved PBS bitmap state. Mail Archive
The VMA fixes only validate archive names and header bounds while reading VMA archives; the official changelog describes them as restore/archive parsing hardening.

A very useful discriminator
If you do the following:
1. install 11.0.3-4;
2. fully stop and start a VM;
3. take no snapshot, perform no migration/rollback/hibernate;
4. observe elevated idle CPU immediately;
then the savevm/migration changes have essentially not been exercised.
That would be strong evidence that the source-level semantic changes above aren't the direct cause.
A guest reboot is not sufficient for this test. You need a QEMU process restart (qm stop / qm start) because replacing the pve-qemu-kvm package on disk does not replace an already-running QEMU process. Proxmox similarly advises starting/migrating VMs afresh when testing a changed QEMU package.
 
Some more findings after comparing -3 to -4 VM with pidstat -t -p "$PID" 1 30 (also GPT output)

Yes — this is a real and fairly specific difference between 11.0.3-3 and 11.0.3-4.

Side-by-side​

pidstat average11.0.3-311.0.3-4Change
whole QEMU process1.03%2.83%2.75×
QEMU main thread0.10%0.97%9.7×
all 4 vCPU threads combined0.93%1.93%2.1×
vCPU00.30%1.07%3.6×
vCPU10.30%0.20%lower
vCPU20.13%0.33%2.5×
vCPU30.20%0.33%1.7×
vhost00unchanged
io_uring worker00unchanged
The -4 averages are explicitly visible at the end of the attached sample. Pasted text

So this is not an io_uring worker issue, not vhost networking, and not nx-lpage recovery.

More importantly, the increase is disproportionately host-side QEMU CPU, not simply the guest doing more work:

  • -3: %usr + %system ≈ 0.73%
  • -4: %usr + %system ≈ 2.04%
  • guest time only rises from 0.30% → 0.80%
About 1.31 percentage points of the 1.80-point regression are host-side QEMU execution.

The strongest clue: exact ~10-second bursts​

Look at -4:

At 19:25:02:

  • whole QEMU: 20%
  • main QEMU thread: 5%
  • vCPU0: 13%
Pasted text

At 19:25:12, exactly 10 seconds later:

  • whole QEMU: 6%
  • main thread: 4%
Pasted text

At 19:25:22, another 10 seconds later:

  • whole QEMU: 19%
  • main thread: 6%
  • vCPU0: 11%
Pasted text

That cadence is highly significant.

pvestatd currently performs its normal status update on a 10-second interval, and its update path invokes the full QEMU VM status collection. GitHub Current qemu-server also explicitly documents that full vmstatus queries KVM through QMP and queues QMP status queries. Proxmox qemu-server vmstatus source

My working hypothesis​

The data now points much more toward:

11.0.3-4 is spending substantially more CPU handling Proxmox's periodic QMP/status collection.
rather than:

the guest simply stopped entering HLT / KVM idle correctly.
The latter would normally show primarily as continuously busier CPU n/KVM threads. Here, the standout change is the QEMU main thread, synchronized to a host-side 10-second timer.

That also makes the savevm-async QIOChannel patch a less convincing direct explanation. Nothing about normal pvestatd polling should exercise save/load VM-state code.


Best next test​

On 11.0.3-4, temporarily stop pvestatd and repeat exactly the same measurement.

VMID=YOUR_VMID
PID=$(cat /run/qemu-server/$VMID.pid)

systemctl stop pvestatd

pidstat -t -p "$PID" 1 30

systemctl start pvestatd
A short stop does not stop the VMs. It does temporarily stop Proxmox status/RRD updates and auto-ballooning, so don't do it during host memory pressure if you're relying on dynamic ballooning.

There are two very useful possible results.

A. CPU falls from ~2.8% toward ~1%​

And the :02/:12/:22 style bursts disappear.

That would be very strong evidence that the regression is specifically triggered by QMP/status polling.

At that point we can isolate which QMP operation is responsible.

B. CPU stays near ~2.8%​

Then the 10-second alignment is coincidental, and we'd switch focus back to:

  • guest timer/interrupt injection;
  • APIC/HPET/RTC behaviour;
  • KVM exits;
  • a QEMU internal periodic timer.

If test A confirms it​

The next step should be perf on the main QEMU thread, because that is where the biggest relative regression is.

For -4:

PID=$(cat /run/qemu-server/$VMID.pid)

perf record \
-F 499 \
-g \
-t "$PID" \
-- sleep 35

perf report --stdio --sort=dso,symbol
PID == main-thread TID, so -t "$PID" deliberately profiles only QEMU's main thread.

Thirty-five seconds covers at least three pvestatd cycles.

I would expect the -4 profile to reveal something in one of these classes:

QMP dispatch
↓
query-blockstats
query-balloon
query-status
QOM/property traversal
block graph iteration
timer/BH processing
Then run the same profile under -3.

The difference between those two main-thread call graphs should be much more diagnostic than aggregate pidstat.


I'd also profile vCPU0 separately​

Your -4 sample has another distinctive feature: the largest QMP/main-thread bursts sometimes coincide with vCPU0 becoming very active.

For example at 19:25:02, vCPU0 accounts for 13%, including 7% guest and 5% system. Pasted text

And at 19:25:22 it reaches 11%. Pasted text

That suggests the main-thread operation may also cause a virtual device event/interrupt that wakes the BSP/vCPU0.

This pattern would fit things such as a device statistics request much better than a generic QEMU busy loop.

To get its TID automatically:

ps -L -p "$PID" -o tid,comm
Then:

perf record -F 499 -g -t VCPU0_TID -- sleep 35
perf report --stdio

One candidate worth testing: balloon statistics​

I wouldn't call it the culprit yet, but virtio-balloon is interesting here.

Proxmox enables the balloon device by default unless explicitly disabled, and QEMU's virtio-balloon statistics mechanism uses a QEMU timer that notifies the guest through a virtqueue when polling statistics. GitHub

That can produce exactly the general shape:

QEMU main thread
│
│ device/timer work
▼
virtio notification
│
▼
guest interrupt
│
▼
vCPU0 wakes
However, Proxmox historically sets balloon guest-stat polling more frequently than 10 seconds, so the 10-second pattern points more directly at pvestatd itself than the balloon timer alone.

If your VM config has:

balloon: ...
or no explicit balloon: 0, I'd keep balloon/QMP memory-stat collection near the top of the candidate list.


What these logs rule out​

I would now give very low priority to:

  • io_uring polling regression — worker is 0%;
  • vhost networking — 0%;
  • nx hugepage recovery — 0%;
  • RCU thread — 0%;
  • one continuously spinning vCPU — load is bursty and spread;
  • a simple guest CPU workload difference — host %usr/%system growth is much too prominent.
The pattern is instead:

11.0.3-4
│
every ~10 seconds
│
▼
QEMU main thread wakes
4–6% for ~1 s
│
sometimes
▼
vCPU0 wakes
up to 11–13%
That is much narrower than where we started.

Current likelihood order​

  1. QMP/status polling interacting differently with the -4 binary
  2. A QMP-triggered virtual-device path, especially memory/balloon/block stats
  3. Rebuild/toolchain/library difference in -4, since none of the seven source commits obviously modifies these paths
  4. Savevm QIOChannel lifetime fix
  5. The other -4 source changes
If you run the 30-second pvestatd-stopped pidstat test, paste that output. That single test should tell us whether to dissect QMP next or abandon that branch entirely.