Good: 7.0.14-15-pve. Bad: 7.0.14-19-pve
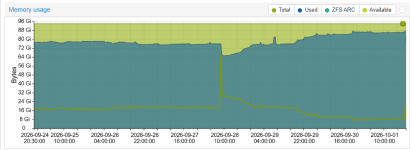
I've noticed after updating from 7.0.14-15 to 7.0.14-19 higher memory usage than usual. It gradually grew over a few days before I noticed it becoming critical, nearing 100%. Shutting the VMs down returned their memory but did not return the extra memory, approx. 16Gb at the time. The unaccounted for memory appeared to grow at approx. 4-5gb/day. I have updated to 7.0.14-20 and rebooted the server about 12 hours ago, so far about 2.5Gb of memory is unaccounted for so it does not appear to have help. The graph below shows my memory usage under 7.0.14-15 up to upgrading and rebooting into 7.0.14-19 and then gradually increase in memory usage after.
I asked an AI for help and feed it some logs, this is what is spat back out at me.
- Growth comes in bursts correlated with activity
- The leak occurs in bursts tied to I/O on raw SATA HDDs passed through to a VM (cache=none, aio=io_uring).
- About 16 GiB of memory missing from /proc/meminfo and from all cgroups, growing about 4–5 GiB/day.
- Not released when any VM is stopped or restarted. It's orphaned until a host reboot.