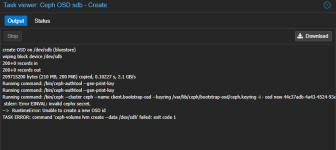
can you post your pvereport (please make sure there is no private information in vm-comments (vm notes) as they are also included in the log.
Instead of sharing the full pvereport output, are there any specific command outputs you need? I can share them, such as pveversion or pveceph status.
Here i shared minimal details with masked information.
=====================================================================================
pveversion --verbose
proxmox-ve: 9.2.0 (running kernel: 7.0.14-25-pve)
pve-manager: 9.2.21 (running version: 9.2.21/4f6e0ac86f9e8c7f)
proxmox-kernel-helper: 9.2.0
proxmox-kernel-7.0: 7.0.14-25
proxmox-kernel-7.0.14-25-pve-signed: 7.0.14-25
proxmox-kernel-7.0.2-6-pve-signed: 7.0.2-6
ceph: 19.2.6-pve4
ceph-fuse: 19.2.6-pve4
corosync: 3.1.10-pve3
criu: 4.1.1-1
frr-pythontools: 10.6.1-1+pve3
ifupdown2: 3.3.0-1+pmx12
intel-microcode: 3.20251111.1~deb13u1
ksm-control-daemon: 1.5-1
libjs-extjs: 7.0.0-7
libproxmox-acme-perl: 1.7.2
libproxmox-backup-qemu0: 2.0.3
libproxmox-rs-perl: 0.4.1
libpve-access-control: 9.1.2
libpve-apiclient-perl: 3.4.3
libpve-cluster-api-perl: 9.1.6
libpve-cluster-perl: 9.1.6
libpve-common-perl: 9.2.3
libpve-guest-common-perl: 6.0.5
libpve-http-server-perl: 6.0.5
libpve-network-perl: 1.6.7
libpve-notify-perl: 9.1.6
libpve-rs-perl: 0.15.3
libpve-storage-perl: 9.1.13
libspice-server1: 0.15.2-1+b1
lvm2: 2.03.31-2+pmx1
lxc-pve: 7.0.0-2
lxcfs: 7.0.0-pve1
novnc-pve: 1.7.0-2
proxmox-backup-client: 4.2.8-1
proxmox-backup-file-restore: 4.2.8-1
proxmox-backup-restore-image: 1.0.0
proxmox-enterprise-support-keyring: 1.1
proxmox-firewall: 1.2.3
proxmox-kernel-helper: 9.2.0
proxmox-mail-forward: 1.0.3
proxmox-mini-journalreader: 1.7
proxmox-offline-mirror-helper: 0.7.4
proxmox-widget-toolkit: 5.2.10
pve-cluster: 9.1.6
pve-container: 6.1.14
pve-docs: 9.2.13
pve-edk2-firmware: 4.2026.08-1
pve-esxi-import-tools: 1.0.1
pve-firewall: 6.0.6
pve-firmware: 3.18-7
pve-ha-manager: 5.2.5
pve-i18n: 3.10.0
pve-qemu-kvm: 11.0.3-4
pve-xtermjs: 6.0.0-2
qemu-server: 9.2.11
smartmontools: 7.5-pve2
spiceterm: 3.4.2
swtpm: 0.8.0+pve3
vncterm: 1.9.2
zfsutils-linux: 2.4.4-pve1
===================================================================
# pveceph status
cluster:
id: 5cbfddefse30-c9d6-4112-aa9d-9212e9dfde3r3f547ffd55
health: HEALTH_ERR
There are daemons running multiple old versions of ceph
clock skew detected on mon.proxmoxvmhost102
services:
mon: 2 daemons, quorum proxmoxvmhost101,proxmoxvmhost102 (age 5d)
mgr: proxmoxvmhost101(active, since 6w), standbys: proxmoxvmhost102
osd: 28 osds: 27 up (since 6w), 27 in (since 4d)
data:
pools: 2 pools, 33 pgs
objects: 233.83k objects, 911 GiB
usage: 2.7 TiB used, 26 TiB / 28 TiB avail
pgs: 33 active+clean
io:
client: 0 B/s rd, 419 KiB/s wr, 0 op/s rd, 40 op/s wr
===================================================================
# ceph df
--- RAW STORAGE ---
CLASS SIZE AVAIL USED RAW USED %RAW USED
hdd 28 TiB 26 TiB 2.7 TiB 2.7 TiB 9.43
TOTAL 28 TiB 26 TiB 2.7 TiB 2.7 TiB 9.43
--- POOLS ---
POOL ID PGS STORED OBJECTS USED %USED MAX AVAIL
.mgr 1 1 1.8 MiB 2 5.4 MiB 0 7.1 TiB
local-nb_prod 2 32 905 GiB 233.83k 2.7 TiB 11.12 7.1 TiB
===================================================================
# ceph osd df tree
ID CLASS WEIGHT REWEIGHT SIZE RAW USE DATA OMAP META AVAIL %USE VAR PGS STATUS TYPE NAME
-1 28.38112 - 28 TiB 2.7 TiB 2.7 TiB 505 KiB 24 GiB 26 TiB 9.43 1.00 - root default
-3 6.54959 - 6.5 TiB 599 GiB 593 GiB 131 KiB 5.2 GiB 6.0 TiB 8.93 0.95 - host proxmoxvmhost101
0 hdd 1.09160 1.00000 1.1 TiB 57 GiB 57 GiB 14 KiB 526 MiB 1.0 TiB 5.13 0.54 2 up osd.0
1 hdd 1.09160 1.00000 1.1 TiB 170 GiB 169 GiB 24 KiB 1.0 GiB 947 GiB 15.25 1.62 6 up osd.1
2 hdd 1.09160 1.00000 1.1 TiB 58 GiB 57 GiB 19 KiB 916 MiB 1.0 TiB 5.15 0.55 2 up osd.2
3 hdd 1.09160 1.00000 1.1 TiB 142 GiB 141 GiB 20 KiB 1.2 GiB 976 GiB 12.69 1.35 5 up osd.3
4 hdd 1.09160 1.00000 1.1 TiB 85 GiB 84 GiB 28 KiB 965 MiB 1.0 TiB 7.60 0.81 3 up osd.4
5 hdd 1.09160 1.00000 1.1 TiB 86 GiB 86 GiB 26 KiB 642 MiB 1.0 TiB 7.72 0.82 3 up osd.5
-5 6.54959 - 6.5 TiB 570 GiB 565 GiB 114 KiB 5.6 GiB 6.0 TiB 8.50 0.90 - host proxmoxvmhost102
6 hdd 1.09160 1.00000 1.1 TiB 142 GiB 141 GiB 14 KiB 787 MiB 976 GiB 12.72 1.35 5 up osd.6
7 hdd 1.09160 1.00000 1.1 TiB 86 GiB 85 GiB 21 KiB 952 MiB 1.0 TiB 7.71 0.82 3 up osd.7
8 hdd 1.09160 1.00000 1.1 TiB 57 GiB 56 GiB 25 KiB 721 MiB 1.0 TiB 5.08 0.54 2 up osd.8
9 hdd 1.09160 1.00000 1.1 TiB 29 GiB 28 GiB 16 KiB 1.0 GiB 1.1 TiB 2.64 0.28 1 up osd.9
10 hdd 1.09160 1.00000 1.1 TiB 113 GiB 112 GiB 9 KiB 863 MiB 1005 GiB 10.12 1.07 5 up osd.10
11 hdd 1.09160 1.00000 1.1 TiB 142 GiB 141 GiB 29 KiB 1.3 GiB 975 GiB 12.74 1.35 5 up osd.11
-7 6.54959 - 6.5 TiB 713 GiB 707 GiB 100 KiB 5.4 GiB 5.9 TiB 10.63 1.13 - host proxmoxvmhost103
12 hdd 1.09160 1.00000 1.1 TiB 113 GiB 112 GiB 16 KiB 1.2 GiB 1004 GiB 10.15 1.08 4 up osd.12
13 hdd 1.09160 1.00000 1.1 TiB 227 GiB 226 GiB 13 KiB 1.1 GiB 891 GiB 20.33 2.16 8 up osd.13
14 hdd 1.09160 1.00000 1.1 TiB 115 GiB 114 GiB 26 KiB 1.3 GiB 1003 GiB 10.30 1.09 4 up osd.14
15 hdd 1.09160 1.00000 1.1 TiB 114 GiB 113 GiB 10 KiB 491 MiB 1004 GiB 10.18 1.08 5 up osd.15
16 hdd 1.09160 1.00000 1.1 TiB 58 GiB 57 GiB 26 KiB 818 MiB 1.0 TiB 5.19 0.55 2 up osd.16
17 hdd 1.09160 1.00000 1.1 TiB 85 GiB 85 GiB 9 KiB 608 MiB 1.0 TiB 7.63 0.81 3 up osd.17
-9 3.27480 - 3.3 TiB 343 GiB 340 GiB 63 KiB 2.6 GiB 2.9 TiB 10.22 1.08 - host proxmoxvmhost104
18 hdd 1.09160 1.00000 1.1 TiB 86 GiB 85 GiB 22 KiB 1.2 GiB 1.0 TiB 7.69 0.82 3 up osd.18
19 hdd 1.09160 1.00000 1.1 TiB 143 GiB 142 GiB 31 KiB 868 MiB 975 GiB 12.79 1.36 5 up osd.19
20 hdd 1.09160 1.00000 1.1 TiB 114 GiB 113 GiB 10 KiB 580 MiB 1004 GiB 10.19 1.08 5 up osd.20
-11 5.45755 - 5.5 TiB 515 GiB 510 GiB 97 KiB 5.1 GiB 5.0 TiB 9.22 0.98 - host proxmoxvmhost06
21 hdd 0.90959 1.00000 931 GiB 29 GiB 28 GiB 20 KiB 669 MiB 902 GiB 3.12 0.33 1 up osd.21
22 hdd 0.90959 1.00000 931 GiB 29 GiB 28 GiB 4 KiB 888 MiB 903 GiB 3.09 0.33 1 up osd.22
23 hdd 0.90959 1.00000 931 GiB 144 GiB 143 GiB 20 KiB 1.2 GiB 788 GiB 15.44 1.64 5 up osd.23
24 hdd 0.90959 1.00000 931 GiB 86 GiB 86 GiB 14 KiB 395 MiB 845 GiB 9.24 0.98 3 up osd.24
25 hdd 0.90959 1.00000 931 GiB 114 GiB 113 GiB 17 KiB 1.2 GiB 817 GiB 12.28 1.30 4 up osd.25
26 hdd 0.90959 1.00000 931 GiB 113 GiB 112 GiB 22 KiB 857 MiB 818 GiB 12.15 1.29 4 up osd.26
27 0 0 0 B 0 B 0 B 0 B 0 B 0 B 0 0 0 down osd.27
TOTAL 28 TiB 2.7 TiB 2.7 TiB 519 KiB 24 GiB 26 TiB 9.43
MIN/MAX VAR: 0.28/2.16 STDDEV: 4.16
==================================================================
# ceph device ls
DEVICE HOST

EV DAEMONS WEAR LIFE EXPECTANCY
HPE_LOGICAL_VOLUME_PEYHC0DRHBD576 proxmoxvmhost103:sdc proxmoxvmhost103:sdd proxmoxvmhost103:sde proxmoxvmhost103:sdf proxmoxvmhost103:sdg proxmoxvmhost103:sdh osd.12 osd.13 osd.14 osd.15 osd.16 osd.17
HPE_LOGICAL_VOLUME_PEYHC0DRHCD5CU proxmoxvmhost101:sdb proxmoxvmhost101:sdc proxmoxvmhost101:sdd proxmoxvmhost101:sde proxmoxvmhost101:sdf proxmoxvmhost101:sdg proxmoxvmhost101:sdh mon.proxmoxvmhost101 osd.0 osd.1 osd.2 osd.3 osd.4 osd.5
HPE_LOGICAL_VOLUME_PWDRE0CRHAV03W proxmoxvmhost104:sdb proxmoxvmhost104:sdc proxmoxvmhost104:sdd osd.18 osd.19 osd.20
HPE_LOGICAL_VOLUME_PWDRE0DRHCR037 proxmoxvmhost102:sdb proxmoxvmhost102:sdc proxmoxvmhost102:sdd proxmoxvmhost102:sde proxmoxvmhost102:sdf proxmoxvmhost102:sdg proxmoxvmhost102:sdh mon.proxmoxvmhost102 osd.10 osd.11 osd.6 osd.7 osd.8 osd.9
HP_LOGICAL_VOLUME_PDNLH0BRH51L1Z proxmoxvmhost06:sdb proxmoxvmhost06:sdc proxmoxvmhost06:sdd proxmoxvmhost06:sde proxmoxvmhost06:sdf proxmoxvmhost06:sdg osd.21 osd.22 osd.23 osd.24 osd.25 osd.26
==================================================================
# cat /etc/ceph/ceph.conf
[global]
auth_client_required = cephx
auth_cluster_required = cephx
auth_service_required = cephx
cluster_network = XX.XX.XX.ZZ/XX
fsid = 5cbfddefse30-c9d6-4112-aa9d-9212e9dfde3r3f547ffd55
mon_allow_pool_delete = true
mon_host = XX.XX.XX.ZZ XX.XX.XX.ZZ
ms_bind_ipv4 = true
ms_bind_ipv6 = false
osd_pool_default_min_size = 2
osd_pool_default_size = 3
public_network = XX.XX.XX.ZZ/XX
[client]
keyring = /etc/pve/priv/$cluster.$name.keyring
[client.crash]
keyring = /etc/pve/ceph/$cluster.$name.keyring
[mon.proxmoxvmhost101]
public_addr = XX.XX.XX.ZZ
[mon.proxmoxvmhost102]
public_addr = XX.XX.XX.ZZ
==================================================================
# ceph config dump
WHO MASK LEVEL OPTION VALUE RO
mon advanced auth_allow_insecure_global_id_reclaim false
# pveceph pool ls
+---------------+------+----------+--------+-------------+----------------+-------------------+--------------------------+---------------------------+-----------------+----------------------+----------+
| Name | Size | Min Size | PG Num | min. PG Num | Optimal PG Num | PG Autoscale Mode | PG Autoscale Target Size | PG Autoscale Target Ratio | Crush Rule Name | %-Used | Used |
+===============+======+==========+========+=============+================+===================+==========================+===========================+=================+======================+==========+
| .mgr | 3 | 2 | 1 | 1 | 1 | on | | | replicated_rule | 2.45213556127055e-07 | 5.45 MiB |
+---------------+------+----------+--------+-------------+----------------+-------------------+--------------------------+---------------------------+-----------------+----------------------+----------+
| local-nb_prod | 3 | 2 | 32 | | 64 | on | | | replicated_rule | 0.111216604709625 | 2.65 TiB |
+---------------+------+----------+--------+-------------+----------------+-------------------+--------------------------+---------------------------+-----------------+----------------------+----------+
# ceph versions
{
"mon": {
"ceph version 19.2.3 (d74d168b1c80fb01e1a30d5e4ca9a45b12bc145b) squid (stable)": 2
},
"mgr": {
"ceph version 19.2.3 (d74d168b1c80fb01e1a30d5e4ca9a45b12bc145b) squid (stable)": 2
},
"osd": {
"ceph version 19.2.3 (d74d168b1c80fb01e1a30d5e4ca9a45b12bc145b) squid (stable)": 18,
"ceph version 19.2.4 (aad7366b93ef26c4157e9bf6347a0900d524d51b) squid (stable)": 3,
"ceph version 19.2.5 (2585b218312ba8cf25c7fe6bc1890e6cfda5949e) squid (stable)": 6
},
"overall": {
"ceph version 19.2.3 (d74d168b1c80fb01e1a30d5e4ca9a45b12bc145b) squid (stable)": 22,
"ceph version 19.2.4 (aad7366b93ef26c4157e9bf6347a0900d524d51b) squid (stable)": 3,
"ceph version 19.2.5 (2585b218312ba8cf25c7fe6bc1890e6cfda5949e) squid (stable)": 6
}
}
==================================================================
# ceph health detail
HEALTH_ERR There are daemons running multiple old versions of ceph; clock skew detected on mon.proxmoxvmhost102
[ERR] DAEMON_OLD_VERSION: There are daemons running multiple old versions of ceph
mon.proxmoxvmhost101 mon.proxmoxvmhost102 osd.0 osd.1 osd.2 osd.3 osd.4 osd.5 osd.6 osd.7 osd.8 osd.9 osd.10 osd.11 osd.12 osd.13 osd.14 osd.15 osd.16 osd.17 mgr.proxmoxvmhost101 mgr.proxmoxvmhost102 are running an older version of ceph: 19.2.3
osd.18 osd.19 osd.20 are running an older version of ceph: 19.2.4
[WRN] MON_CLOCK_SKEW: clock skew detected on mon.proxmoxvmhost102
mon.proxmoxvmhost102 clock skew 0.426234s > max 0.05s (latency 0.000574145s)
==================================================================