

Hi.
We use a 5 node cluster, that looks like that:
Location A "UR":
- SRVURPVE01
- SRVURPVE02
Location B "ZH":
- SRVZHPVE01
- SRVZHPVE02
Cloud - ISP:
-SRVPVEMON01
The locations A and B are linked with each other over 2x25gbit Darkfiber and have a latency of 0.170ms node to node.
The Monitor in the ISP cloud has a latency of 3-4ms and is connected via S2S Wireguard to both locations with 3-4ms latency node to node.
As you would expect, the Monitor exists only as that. A PVE Quorum device, Ceph Mon and Manager. Hence, an affinity rule in HA was put into place to strictly avoid this node.
In this rule, almost all HA enabled machines were tagged, with some exceptions.
Exceptions are f.e. Domain Controllers, Storage controllers (for old vSphere environment) and so on.
Those are tagged in a prefer node affinity rule like:
OfficeDC01 -> Prefer SRVURPVE01 & SRVURPVE02
OfficeDC02 -> Prefer SRVZHPVE01 & SRVZHPVE02
because the secondary system will be running in the Datacenter at the other location anyways.
However, if we now want to make network changes in one Datacenter location, we need to take both nodes there into maintenance mode, which makes CRS Start migrating VMs to the other Datacenter, except the DCs for example. CRS wants to migrate those to SRVURPVEMON01, which it can't, because it's missing the Network interface for the VMs and Ceph connection.
Easy, you'd think. Just include the VMs to the Avoid nodes affinity rule. But that's my problem:
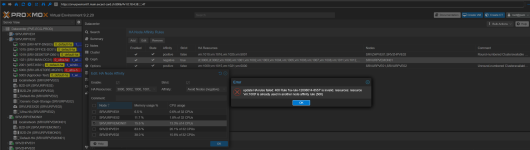
"update HA rules failed: 400 Rule 'ha-rule-12008014-8557' is invalid. resources: resource 'vm:1009' is already used in another node affinity rule (500)"
If anyone else ran into that issue also, how did you solve that?
Happy to hear from you.
Regards, Nick.
We use a 5 node cluster, that looks like that:
Location A "UR":
- SRVURPVE01
- SRVURPVE02
Location B "ZH":
- SRVZHPVE01
- SRVZHPVE02
Cloud - ISP:
-SRVPVEMON01
The locations A and B are linked with each other over 2x25gbit Darkfiber and have a latency of 0.170ms node to node.
The Monitor in the ISP cloud has a latency of 3-4ms and is connected via S2S Wireguard to both locations with 3-4ms latency node to node.
As you would expect, the Monitor exists only as that. A PVE Quorum device, Ceph Mon and Manager. Hence, an affinity rule in HA was put into place to strictly avoid this node.
In this rule, almost all HA enabled machines were tagged, with some exceptions.
Exceptions are f.e. Domain Controllers, Storage controllers (for old vSphere environment) and so on.
Those are tagged in a prefer node affinity rule like:
OfficeDC01 -> Prefer SRVURPVE01 & SRVURPVE02
OfficeDC02 -> Prefer SRVZHPVE01 & SRVZHPVE02
because the secondary system will be running in the Datacenter at the other location anyways.
However, if we now want to make network changes in one Datacenter location, we need to take both nodes there into maintenance mode, which makes CRS Start migrating VMs to the other Datacenter, except the DCs for example. CRS wants to migrate those to SRVURPVEMON01, which it can't, because it's missing the Network interface for the VMs and Ceph connection.
Easy, you'd think. Just include the VMs to the Avoid nodes affinity rule. But that's my problem:
"update HA rules failed: 400 Rule 'ha-rule-12008014-8557' is invalid. resources: resource 'vm:1009' is already used in another node affinity rule (500)"
If anyone else ran into that issue also, how did you solve that?
Happy to hear from you.
Regards, Nick.
