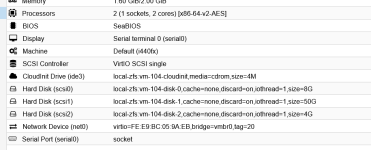
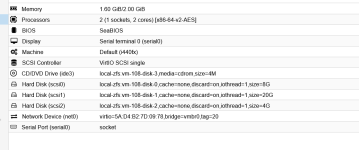
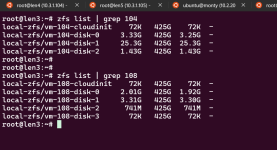
Update with much better data, and I think I've found the trigger. It's HA **recovery** after a node shutdown, not migration and not Terraform: nothing ran Terraform this time.
**What it looks like in practice:** a routine two-node maintenance gets stuck halfway.
1. I shut down len2 for hardware maintenance. Its HA VMs moved to len1 and came back up, so all looked fine. In fact they weren't migrated: under the default `shutdown_policy=conditional`, HA stopped them and restarted them on len1, with about six minutes of downtime.
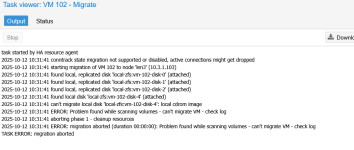
2. len2 came back, and I put len1 into maintenance to do the same to it. Now the VMs **couldn't move back to len2**. Every migration failed with `volume 'local-zfs/vm-<id>-cloudinit' already exists`, and HA retried them every ~10 s indefinitely. len1 couldn't be drained until I deleted the stale cloud-init volumes on len2 by hand.
The details and logs are below.
**Setup:** PVE 9.2.21, 5-node cluster, HA, ZFS (`local-zfs`) replication. Cloud-init drive on local ZFS (not replicated, as expected).
Code:
proxmox-ve: 9.2.0 (running kernel: 7.0.14-24-pve)
pve-manager: 9.2.21 (running version: 9.2.21/4f6e0ac86f9e8c7f)
libpve-storage-perl: 9.1.13
pve-ha-manager: 5.2.5
qemu-server: 9.2.11
zfsutils-linux: 2.4.4-pve1
VM 107: HA resource (`failback 1`), replication job `107-0` between len2 and len1 every 10 minutes.
Code:
cores: 2
ide3: local-zfs:vm-107-cloudinit,media=cdrom,size=4M
memory: 1024
ostype: other
scsi0: local-zfs:vm-107-disk-0,cache=none,discard=on,iothread=1,size=8G
scsi1: local-zfs:vm-107-disk-1,cache=none,discard=on,iothread=1,size=8G
scsi2: local-zfs:vm-107-disk-2,backup=0,cache=none,discard=on,iothread=1,size=2G
**Steps to reproduce:**
1. An HA VM with replicated disks and a cloud-init drive on local ZFS runs on node A (len2), replicating to node B (len1).
2. Shut down node A with the default HA `shutdown_policy=conditional`. On a shutdown, as opposed to a reboot, that means failover.
3. HA recovers the VM by **starting** it on node B. Node B creates a **new** cloud-init volume.
4. Node A comes back. Replication handles the replicated disks, but **the old `vm-<id>-cloudinit` on node A is never removed.**
5. Any later migration B → A fails with `volume 'local-zfs/vm-<id>-cloudinit' already exists`. HA retries it every ~10 s indefinitely, so the node can't be put into maintenance.
**Evidence:**
Node A (len2) shuts down. The LRM stops the VM under `conditional`:
Code:
Nov 04 21:24:59 len2 pve-ha-lrm[1878]: got shutdown request with shutdown policy 'conditional'
Nov 04 21:24:59 len2 pve-ha-lrm[1878]: shutdown LRM, stop all services
Nov 04 21:25:00 len2 pve-ha-lrm[1217690]: stopping service vm:107
Nov 04 21:25:12 len2 pve-ha-lrm[1217690]: <root@pam> end task UPID:len2:0012949C:0A89A365:6AEAEBDC:qmshutdown:107:root@pam: OK
Nov 04 21:25:12 len2 pve-ha-lrm[1217690]: service status vm:107 stopped
Nov 04 21:25:13 len2 pve-ha-lrm[1878]: server stopped
Node B (len1) recovers it with a start, not a migration:
Code:
Nov 04 21:26:22 len1 pve-ha-lrm[912906]: starting service vm:107
Nov 04 21:31:23 len1 pve-ha-lrm[912906]: service status vm:107 started
Nov 04 21:34:29 len1 pve-ha-crm[1779]: node 'len2': state changed from 'unknown' => 'online'
…and creates a fresh cloud-init volume (`zpool history` on len1), not one received from len2:
Code:
2026-11-04.21:31:21 zfs create -s -V 4096k local-zfs/vm-107-cloudinit [user 0 (root) on len1:linux]
On node A (len2), the old volume was received on 15 Oct by a normal migration. Nothing touches it after that until I deleted it by hand on 4 Nov at 21:40. The 15 Oct lines also show that a normal migration cleans up correctly: send, then `destroy -r` on the source.
Code:
2026-10-15.10:17:54 zfs snapshot local-zfs/vm-107-cloudinit@__migration__ [user 0 (root) on len2:linux]
2026-10-15.10:17:55 zfs send -RpvU -- local-zfs/vm-107-cloudinit@__migration__ [user 0 (root) on len2:linux]
2026-10-15.10:17:55 zfs destroy local-zfs/vm-107-cloudinit@__migration__ [user 0 (root) on len2:linux]
2026-10-15.10:18:24 zfs destroy -r local-zfs/vm-107-cloudinit [user 0 (root) on len2:linux]
2026-10-15.10:20:28 zfs recv -F -x encryption -- local-zfs/vm-107-cloudinit [user 0 (root) on len2:linux]
2026-10-15.10:20:28 zfs destroy local-zfs/vm-107-cloudinit@__migration__ [user 0 (root) on len2:linux]
2026-11-04.21:40:30 zfs destroy -r local-zfs/vm-107-cloudinit [user 0 (root) on len2:linux]   <- my manual cleanup
Putting len1 into maintenance then failed for every retry of 107 (and 113, same pattern):
Code:
2026-11-04 21:36:25 full send of local-zfs/vm-107-cloudinit@__migration__ estimated size is 81.5K
2026-11-04 21:36:26 volume 'local-zfs/vm-107-cloudinit' already exists
send/receive failed, cleaning up snapshot(s)..
2026-11-04 21:36:26 ERROR: storage migration for 'local-zfs:vm-107-cloudinit' to storage 'local-zfs' failed - command 'set -o pipefail && pvesm export local-zfs:vm-107-cloudinit zfs - -with-snapshots 0 -snapshot __migration__ | /usr/bin/ssh -e none -o 'BatchMode=yes' -o 'HostKeyAlias=len2' -o 'UserKnownHostsFile=/etc/pve/nodes/len2/ssh_known_hosts' -o 'GlobalKnownHostsFile=none' root@10.3.1.102 -- pvesm import local-zfs:vm-107-cloudinit zfs - -with-snapshots 0 -snapshot __migration__ -delete-snapshot __migration__ -allow-rename 0' failed: exit code 255
2026-11-04 21:36:26 ERROR: migration aborted (duration 00:00:07): storage migration for 'local-zfs:vm-107-cloudinit' to storage 'local-zfs' failed
TASK ERROR: migration aborted
After I removed the stale volume on len2 (`pvesm free local-zfs:vm-107-cloudinit`), the next migration went through, and it cleaned up the source as expected.
This explains what I saw originally: it looked random, roughly weekly, "overnight". It happens after any node shutdown or failure that HA recovers from, and then it surfaces at the next migration. It also explains
@jt_telrite's case without Terraform.
**Suggested fix:** since the cloud-init volume is generated content, either
- migration could overwrite or replace an existing `vm-<id>-cloudinit` on the target, or
- recovery, or replication's cleanup when the node rejoins, could remove the stale cloud-init volume on the old node.
Mitigation in the meantime: shutdown_policy=migrate (or always entering maintenance mode first), so a planned shutdown live-migrates instead of recovering. Live migration cleans up the source's cloud-init volume, so no stale copy is left. It doesn't help once a stale volume already exists (that migration fails the same way), and it doesn't cover a real node failure.
Related: this looks like the case Daniel Kral raised on pve-devel in March (forum thread 181516, recovery after fencing), in the thread for "migration: prohibit renaming cloud-init drive":
https://lore.proxmox.com/pve-devel/DGZ5VVU45RP2.UJNEF7OMOJ0Q@proxmox.com/T/#t . That patch also explains my original symptom here: before it, the leftover volume made migration rename the new cloud-init disk to vm-<id>-disk-N, which then showed up as an ordinary disk. Now it fails with "already exists" instead. Same root cause, a cloud-init volume left on the old node after recovery. This report adds that a plain planned shutdown with the default shutdown_policy=conditional is enough to trigger it.
I'll post it on Bugzilla and link it here