jsterr's latest activity
-
 jsterr reacted to iss-integration's post in the thread Ceph CVEs – keyring rotation strongly advised, probably required in the future with
 Like.
--rotate-lockbox-keys worked well on our 3 node 12-OSD test cluster. The warnings are now gone. We'll be testing further with other clusters and report any issues.
-
jsterr replied to the thread PVE 9.2 + Ceph Tentacle 20.2.4: RBD operations fail because pve-storage passes removed --auth_supported option.Fix is up and worked well on my side: https://forum.proxmox.com/threads/ceph-cves-–-keyring-rotation-strongly-advised-probably-required-in-the-future.185863/#post-867260
-
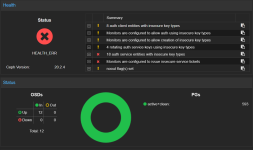
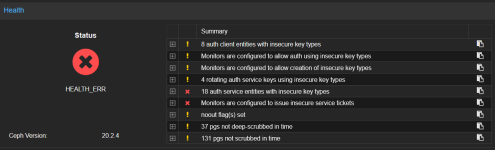
jsterr replied to the thread Ceph CVEs – keyring rotation strongly advised, probably required in the future.Hello Thomas! @t.lamprecht After applying the updates in the script its green again, had to use a couple of commands though: root@training3:~# /usr/share/pve-manager/migrations/pve-cephx-rotate-service-keys root@training3:~#...
-
-
jsterr replied to the thread Proxmox VE Ceph Benchmark 2023/12 - Fast SSDs and network speeds in a Proxmox VE Ceph Reef cluster.how did it help you exactly? ;-) I personally would like to make some testing about: * testing with 32 PGs vs 512 PGs (min/max) and how it affects performance * testing with erasure coded pools (fastec/non-fast-ec) * testing with krbd/non-krbd
-
jsterr replied to the thread Questions about the dynamic CRS.Yeah the container has failback disabled, this seems to be the reason why the container can be moved to a different host, even though the other host has a lower priority.
-
This should be the same for VMs and CTs as the HA Manager handles affinity rules the same for both. In a quick test, the migration blocker with the same node affinity rule as above was shown to me for both VMs and CTs, so I couldn't move either...
-
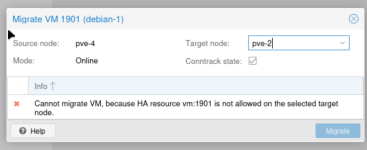
jsterr replied to the thread Questions about the dynamic CRS.Hi @dakralex is this a known bug? If not I would create a new one. (not related to dynamic crs but we had talked about other ha improvements here in the last posts) Bug: VMs cant be migrated to nodes with lower priority if priority is set in a...
-
-
jsterr replied to the thread PVE 9.2 + Ceph Tentacle 20.2.4: RBD operations fail because pve-storage passes removed --auth_supported option.20.2.4-pve2 released - seems like I need to manually remove the self-applied fix, as the dashboard still shows the errors.
-
jsterr replied to the thread PVE 9.2 + Ceph Tentacle 20.2.4: RBD operations fail because pve-storage passes removed --auth_supported option.for reference. I also used the workaround by editing the file.
-
-
-
jsterr replied to the thread Questions about the dynamic CRS.Hallo Daniel! Done https://bugzilla.proxmox.com/show_bug.cgi?id=7893 https://bugzilla.proxmox.com/show_bug.cgi?id=6593 (this ones already existing but also useful) https://bugzilla.proxmox.com/show_bug.cgi?id=6960 (already existed, commented on...
-
jsterr reacted to aaron's post in the thread Feedback on the bulk-restart feature of ceph (9.2.5) with Like.
@jsterr please add/create a bug/enhancement request over at https://bugzilla.proxmox.com/ Thanks!
-
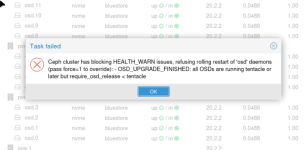
jsterr posted the thread Feedback on the bulk-restart feature of ceph (9.2.5) in Proxmox VE: Installation and configuration.Hello Kefu Chai (does he have a account here @aaron ?) Nice addition of having a bulk-restart feature in ceph when using 9.2.5 :-) It worked really well on mons, mgr, osds and mds. I also used it in a test-setup for trying a ceph 19 to 20...
-
-
Generally, these sound like good ideas! Feel free to create separate Bugzilla entries for the separate issues: automatically add new guests as HA resources by enabling some cluster-wide check (Though new guests can be automatically added...
-
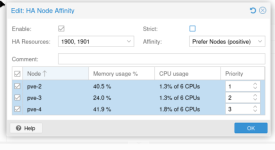
jsterr replied to the thread Questions about the dynamic CRS.Hi Daniel! Some cases that do not work or might be cool adding them: Example 1: A resource affinity rule with “Keep Separate” for VM1 and VM2, combined with an HA node affinity rule (without “Strict”) on node1 and node2 (checked), but not...
-
-
Hi, sorry for the late reply! At least for two rooms this is already possible with non-strict node affinity rules as these will fallback to the other available cluster nodes if none of the specified nodes are available anymore. However, an HA...
-
A few notes based on our experience with NVMe/TCP and PVE: Your performance expectation should come from your storage stack, not your choice of protocol. The transport is usually not the bottleneck in setups like this. If you're seeing latencies...
-
jsterr replied to the thread Proxmox VE Ceph Benchmark 2023/12 - Fast SSDs and network speeds in a Proxmox VE Ceph Reef cluster.Full meshed with sdn fabric (openfabric) is the way to go. See the 9.0 Release Video for a quick introduction.
-
Hey! just sharing my two cents here of what I have tried so far. nvme-cli vs nvme-stas: We recently had this conversation with a customer. First we configured it with nvme-cli natively, but this turned out to be rather complex. It works, but...