I tested kernel-7.0.14-22_bnxt-test1, in my case, the problem is gone, there are no issues in the logs regarding the bnxt_en driver, and the network is working.


Proxmox VE 9.2.21 - BCM57412 bnxt_en network failure after upgrade to kernel 7.0.14-20-pve
- Thread starter ManuS
- Start date
You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.

Just to clarify, how long does it take from the test kernel release until it becomes available on the production/stable channel for download and update?
Over 2 hours in to running today's 7.0.14-22~bnxt-test1, so issues at all so far. I've even done a 5 minute iperf3 in both directions over the bnxt_en adapters, and no issues what so ever.
Same problem whit my BCM57502
Linux amd2 7.0.14-20-pve #1 SMP PREEMPT_DYNAMIC PMX 7.0.14-20 (2026-09-24T10:43Z) x86_64 GNU/Linux
root@amd2:~# lspci -nn -s 02:00.002:00.0 Ethernet controller [0200]: Broadcom Inc. and subsidiaries BCM57502 NetXtreme-E 10Gb/25Gb/40Gb/50Gb Ethernet [14e4:1752] (rev 12)root@amd2:~# ethtool -i nic0driver: bnxt_enversion: 7.0.14-20-pvefirmware-version: 229.0.121.0/pkg N/Aexpansion-rom-version: bus-info: 0000:02:00.0supports-statistics: yessupports-test: yessupports-eeprom-access: yessupports-register-dump: yessupports-priv-flags: noroot@amd2:~# devlink dev info pci/0000:02:00.0pci/0000:02:00.0: driver bnxt_en serial_number 9C-6B-00-FF-FE-CD-8B-D8 board.serial_number 0123456789ABCDEFGH versions: fixed: board.id B650D4U3-2L2Q/BCM asic.id 1752 asic.rev B2 running: fw.psid 0.0.28 fw N/A fw.mgmt 229.0.121.0 fw.mgmt.api 1.10.3 stored: fw.psid 0.0.28 fw N/A fw.mgmt 229.0.121.0
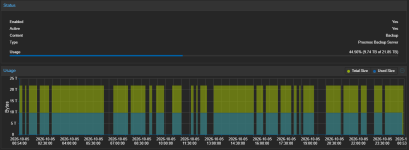
Attached txt file is kernel msg for bnxt_en
And png file is this NIC BCM57502 connection to backup server - and random drops.
Have a nice day!
Attachments
Last edited:
kernel-7.0.14-22_bnxt-test1is running about 18h now without any problems. It seems that this has resolved the issue, since with the problematic kernel 7.0.14-20, the network would always go down after 5 minutes at the latest.
Same issue here, on different hardware and with newer NIC firmware, so in my case a firmware update alone does not seem to be the fix.
Setup
Observations on 7.0.14-20-pve
The firmware crashes on every boot, about 20–25 s after driver init and without any load. The event codes are identical each time:
The first time, the card recovered by itself. About 10 minutes later, during a live migration, it hung for good:
Both ports went down, and the node lost its storage network.
IOMMU faults: every firmware crash on -20 coincides with a DMAR fault from the same NIC (Intel platform, IOMMU in translated mode). There are no DMAR faults on 7.0.14-17:
So it looks like the NIC is doing DMA to an address that is no longer (or not yet) mapped in the IOMMU, which then triggers the firmware fatal reset. That points to a DMA mapping change in bnxt_en or intel-iommu between -17/-19 and -20, rather than to the NIC firmware itself.
Workaround: booted 7.0.14-17-pve (the previous kernel on this host). There have been no firmware events since, including heavy live migrations. The other two nodes (same hardware) stay on 7.0.14-17 without issues.
Attached: bnxt-related kernel messages from both failing boots (filtered and deduplicated) and
Setup
- HPE ProLiant DL360 Gen11, 3-node PVE 9.2 cluster
- Broadcom BCM57412 NetXtreme-E Dual 10Gb SFP+ OCP 3.0 (bnxt_en)
- NIC firmware:
237.1.141.0/pkg 237.1.148.0(newer than the 236.x mentioned above) - Both ports in an active-backup bond, MTU 9000, used for DRBD/LINSTOR storage and migration
Observations on 7.0.14-20-pve
The firmware crashes on every boot, about 20–25 s after driver init and without any load. The event codes are identical each time:
Code:
07:23:24 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27, min wait 1300 ms, max wait 4200 ms
07:23:29 bnxt_en 0000:3c:00.1 nic5: TX timeout detected, starting reset task!
The first time, the card recovered by itself. About 10 minutes later, during a live migration, it hung for good:
Code:
07:33:08 bnxt_en 0000:3c:00.0 nic4: TX timeout detected, starting reset task!
07:33:08 bnxt_en 0000:3c:00.0 nic4: Abandoning msg {0xb1 0xd0b} len: 0 due to firmware status: 0x2000001
07:33:08 bnxt_en 0000:3c:00.0 nic4: hwrm stat ctx alloc failure rc: fffffff0
07:33:08 bnxt_en 0000:3c:00.0 nic4: nic open fail (rc: fffffff0)modprobe -r bnxt_en && modprobe bnxt_en brought the link back temporarily. After a full power off/on via iLO, still on -20, the same thing happened again 20 s after boot:
Code:
08:02:27 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27, min wait 1300 ms, max wait 4200 ms
08:02:29 bnxt_en 0000:3c:00.1 nic5: Abandoning msg {0x23 0x437} len: 0 due to firmware status: 0x2000001
08:02:33 bnxt_en 0000:3c:00.1 nic5: NETDEV WATCHDOG: CPU: 50: transmit queue 1 timed out 5632 ms
IOMMU faults: every firmware crash on -20 coincides with a DMAR fault from the same NIC (Intel platform, IOMMU in translated mode). There are no DMAR faults on 7.0.14-17:
Code:
07:23:24 DMAR: [DMA Read NO_PASID] Request device [3c:00.1] fault addr 0xdc669000 [fault reason 0x71] SM: Present bit in first-level paging entry is clear
07:23:24 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27
07:33:02 DMAR: [DMA Read NO_PASID] Request device [3c:00.0] fault addr 0xe2e2a000 [fault reason 0x71] SM: Present bit in first-level paging entry is clear
07:33:08 bnxt_en 0000:3c:00.0 nic4: TX timeout detected, starting reset task!
08:02:27 DMAR: [DMA Read NO_PASID] Request device [3c:00.1] fault addr 0xdc698000 [fault reason 0x71] SM: Present bit in first-level paging entry is clear
08:02:27 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27Workaround: booted 7.0.14-17-pve (the previous kernel on this host). There have been no firmware events since, including heavy live migrations. The other two nodes (same hardware) stay on 7.0.14-17 without issues.
Attached: bnxt-related kernel messages from both failing boots (filtered and deduplicated) and
pveversion -v. Full logs are available on request.Attachments
Can you try test kernel found here https://forum.proxmox.com/threads/p...de-to-kernel-7-0-14-20-pve.186749/post-871933 so far it seems to fix the issueSame issue here, on different hardware and with newer NIC firmware, so in my case a firmware update alone does not seem to be the fix.
Setup
- HPE ProLiant DL360 Gen11, 3-node PVE 9.2 cluster
- Broadcom BCM57412 NetXtreme-E Dual 10Gb SFP+ OCP 3.0 (bnxt_en)
- NIC firmware:
237.1.141.0/pkg 237.1.148.0(newer than the 236.x mentioned above)- Both ports in an active-backup bond, MTU 9000, used for DRBD/LINSTOR storage and migration
Observations on 7.0.14-20-pve
The firmware crashes on every boot, about 20–25 s after driver init and without any load. The event codes are identical each time:
Code:07:23:24 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27, min wait 1300 ms, max wait 4200 ms 07:23:29 bnxt_en 0000:3c:00.1 nic5: TX timeout detected, starting reset task!
The first time, the card recovered by itself. About 10 minutes later, during a live migration, it hung for good:
Both ports went down, and the node lost its storage network.Code:07:33:08 bnxt_en 0000:3c:00.0 nic4: TX timeout detected, starting reset task! 07:33:08 bnxt_en 0000:3c:00.0 nic4: Abandoning msg {0xb1 0xd0b} len: 0 due to firmware status: 0x2000001 07:33:08 bnxt_en 0000:3c:00.0 nic4: hwrm stat ctx alloc failure rc: fffffff0 07:33:08 bnxt_en 0000:3c:00.0 nic4: nic open fail (rc: fffffff0)
modprobe -r bnxt_en && modprobe bnxt_enbrought the link back temporarily. After a full power off/on via iLO, still on -20, the same thing happened again 20 s after boot:
Code:08:02:27 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27, min wait 1300 ms, max wait 4200 ms 08:02:29 bnxt_en 0000:3c:00.1 nic5: Abandoning msg {0x23 0x437} len: 0 due to firmware status: 0x2000001 08:02:33 bnxt_en 0000:3c:00.1 nic5: NETDEV WATCHDOG: CPU: 50: transmit queue 1 timed out 5632 ms
IOMMU faults: every firmware crash on -20 coincides with a DMAR fault from the same NIC (Intel platform, IOMMU in translated mode). There are no DMAR faults on 7.0.14-17:
So it looks like the NIC is doing DMA to an address that is no longer (or not yet) mapped in the IOMMU, which then triggers the firmware fatal reset. That points to a DMA mapping change in bnxt_en or intel-iommu between -17/-19 and -20, rather than to the NIC firmware itself.Code:07:23:24 DMAR: [DMA Read NO_PASID] Request device [3c:00.1] fault addr 0xdc669000 [fault reason 0x71] SM: Present bit in first-level paging entry is clear 07:23:24 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27 07:33:02 DMAR: [DMA Read NO_PASID] Request device [3c:00.0] fault addr 0xe2e2a000 [fault reason 0x71] SM: Present bit in first-level paging entry is clear 07:33:08 bnxt_en 0000:3c:00.0 nic4: TX timeout detected, starting reset task! 08:02:27 DMAR: [DMA Read NO_PASID] Request device [3c:00.1] fault addr 0xdc698000 [fault reason 0x71] SM: Present bit in first-level paging entry is clear 08:02:27 bnxt_en 0000:3c:00.0 nic4: Fatal firmware reset event, data1: 0x201, data2: 0xda27
Workaround: booted 7.0.14-17-pve (the previous kernel on this host). There have been no firmware events since, including heavy live migrations. The other two nodes (same hardware) stay on 7.0.14-17 without issues.
Attached: bnxt-related kernel messages from both failing boots (filtered and deduplicated) andpveversion -v. Full logs are available on request.
Not directly related to this Kernel bug but HPE released new firmware files (238.1.168.0) for serveral Broadcom NIC's.
Code:
This product fixes an issue where retransmitted NC-SI responses could use an incorrect MCTP tag, causing the response to be discarded or misrouted.
This product fixes an issue where ports without pluggable optical modules could incorrectly report the module status as "Not Inserted" instead of "Not Applicable."We experienced the very same issue with kernel-7.0.14-20-pve and Broadcom network adapters (Broadcom Adv. Quad 25Gb Ethernet) in a Dell PowerEdge 770 server.
System is booting, but network connectivity is extremely instable and causes frequent reboots.
Firmware 38.11.38.06 (latest firmware that iDRAC offered to install)
Switching back to kernel 7.0.14-3-pve solved the problem.
System is booting, but network connectivity is extremely instable and causes frequent reboots.
Firmware 38.11.38.06 (latest firmware that iDRAC offered to install)
Switching back to kernel 7.0.14-3-pve solved the problem.
Test result for 7.0.14-22~bnxt-test1 on Intel (HPE DL360 Gen11, BCM57412, NIC firmware 237.1.141.0):Can you try test kernel found here https://forum.proxmox.com/threads/p...de-to-kernel-7-0-14-20-pve.186749/post-871933 so far it seems to fix the issue
- No
Fatal firmware reset event, no TX timeouts and no DMAR faults since boot. On -20 the first crash came 20–25 s after driver init, on every boot. - Load test: live migrations of 24 GB and 32 GB VMs to and from this node over the bnxt_en bond, at ~1 GB/s. This is exactly the scenario that killed the NIC on -20. No issues.
- DRBD/LINSTOR storage traffic over the same NICs is stable.
So the fix works on Intel / intel-iommu as well. Thanks for the quick turnaround!
Yeah i want to know also, atm i am on kernel .19 pinned everywhere.Just to clarify, how long does it take from the test kernel release until it becomes available on the production/stable channel for download and update?
kernel -22 was released earlier today. it worked for my (not directly related to this) problemYeah i want to know also, atm i am on kernel .19 pinned everywhere.
Feedback on kernel 7.0.14-22-pve
We experienced instability with previous kernel releases on our Proxmox cluster, particularly after upgrading from 7.0.14-16-pve.
Today we tested 7.0.14-22-pve on one node. After approximately 30 minutes of uptime, the node appears stable:
We will continue monitoring and provide an update after a longer uptime period.
We experienced instability with previous kernel releases on our Proxmox cluster, particularly after upgrading from 7.0.14-16-pve.
Today we tested 7.0.14-22-pve on one node. After approximately 30 minutes of uptime, the node appears stable:
- No unexpected reboots
- No kernel panics
- No obvious issues in dmesg/journal logs
- Cluster services and Ceph operating normally
We will continue monitoring and provide an update after a longer uptime period.
Same issue here. With kernel 7.0.14-20-pve and Supermicro AOC-STG-b2T-NI22 (based on BCM57416) updated to firmware 237.1.148.0, the system is not stable and network comes and goes every few minutes. Using kernel 7.0.14-16-pve is fine. I am gonna test 7.0.14-22-pve shortly.
In our lab we were hit with this issue due to running BCM57412 bnxt_en Nics when we updated to the .14-20 kernel. We pinned to .14-19 as a workaround.
Today I updated to the .14.22 kernel and so far no issues seen.
Today I updated to the .14.22 kernel and so far no issues seen.
Last edited:
Having the same issue with Broadcom BCM57414 Dual 25Gb adapter, on a DELL PowerEdge R6515 with an AMD EPYC CPU and PVE 9 kernel 7.0.14-20-pve.
Also using Linux bond, in active-backup mode. There are two bonds on each server - only the second bond stopped working (luckily it's not the one that carries management VLAN), but that bond is using the secondary 10G port from the same Broadcom adapter. The primary bond, that continued to work was using the first 10G port on that same adapter. Primary bond (the one that worked) is connected to a switch. The second bond is actually a direct connection between the servers themselves. Don't know if that is important.
Journal log attached.
My Broadcom firmware is 38.11.38.06 and iDRAC is not offering anything newer.
Using the 7.0.14-19-pve kernel solved the issue for me as well.
I can confirm that 7.0.14-22-pve kernel has resolved the issue.
iDRAC is also offering newer firmware for the Broadcom network card on my servers that have cards of that brand, new version is 38.11.70.00.
Yes, confirmed 7.0.14-22 works fine.
Here my experience:
7.0.14-16 - FW 223.0.161.0 >> Working
7.0.14-20 - FW 223.0.161.0 >> NOT Working
7.0.14-20 - FW 234.1.124.0 >> NOT Working
7.0.14-20 - FW 237.1.148.0 >> NOT Working
7.0.14-22 - FW 237.1.148.0 >> Working
Here my experience:
7.0.14-16 - FW 223.0.161.0 >> Working
7.0.14-20 - FW 223.0.161.0 >> NOT Working
7.0.14-20 - FW 234.1.124.0 >> NOT Working
7.0.14-20 - FW 237.1.148.0 >> NOT Working
7.0.14-22 - FW 237.1.148.0 >> Working
I have still problems with my 10G Broadcom Nic. After 2-24h the link is gone and only a reboot is making it working again:
The relevant Log entries are:
I read a blog post regarding this issue:
https://freenode.net/article/bnxt-en-dma-faults-after-link-layer-headroom-change
Does somebody know if the mentioned fix in the driver is already part of .22 kernel Version?
Kind regards
Dominik
The relevant Log entries are:
Code:
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfea8d80 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfcb9a80 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfd4f300 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfe7a180 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfd5a8c0 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfb59000 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbef61c40 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbeb2e740 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbd730f40 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.0: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbc7a9e00 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfefcce8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfca34a8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbd5b5e68 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbeb2b4a8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbc7b60e8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xfed8a4a8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xfed5f4a8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfcf70e8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbf8fc8e8 flags=0x0000]
Oct 09 04:34:32 kvm1 kernel: bnxt_en 0000:10:00.1: AMD-Vi: Event logged [IO_PAGE_FAULT domain=0x000c address=0xbfc279a8 flags=0x0000]
Oct 09 04:34:33 kvm1 kernel: bnxt_en 0000:10:00.0 enp16s0f0np0: Error (timeout: 500015) msg {0x23 0xa9b4} len:0
Oct 09 04:34:34 kvm1 kernel: bnxt_en 0000:10:00.0 enp16s0f0np0: Error (timeout: 500015) msg {0xb4 0xa9b5} len:0
Oct 09 04:34:35 kvm1 kernel: bnxt_en 0000:10:00.1 enp16s0f1np1: Error (timeout: 500015) msg {0x23 0xa9b3} len:0
Oct 09 04:34:36 kvm1 kernel: bnxt_en 0000:10:00.1 enp16s0f1np1: Error (timeout: 500015) msg {0xb4 0xa9b4} len:0
Oct 09 04:34:37 kvm1 kernel: bnxt_en 0000:10:00.0 enp16s0f0np0: Error (timeout: 500015) msg {0x23 0xa9b6} len:0
Code:
root@kvm1:~# ethtool -i enp16s0f0np0
driver: bnxt_en
version: 7.0.14-22-pve
firmware-version: 214.0.207.0/pkg 214.0.207.0
expansion-rom-version:
bus-info: 0000:10:00.0
supports-statistics: yes
supports-test: yes
supports-eeprom-access: yes
supports-register-dump: yes
supports-priv-flags: no
I read a blog post regarding this issue:
https://freenode.net/article/bnxt-en-dma-faults-after-link-layer-headroom-change
Does somebody know if the mentioned fix in the driver is already part of .22 kernel Version?
Kind regards
Dominik
