Hardware clock access missing => em28xx crash causing reboot to fail

leesteken

Distinguished Member
May 31, 2020
8,255
3,008
278
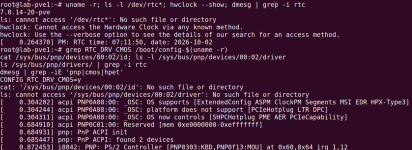
I use rtcwake to shutdown my Proxmox host (and run hwclock --systohc as root just before that) and this worked fine for many years including kernel 7.0.14-19.

The recent (no-subscription) proxmox-kernel-7.0.14-20-pve-signed breaks this and shows the following in the system log:
Code:
hwclock: Cannot access the Hardware Clock via any known method.
hwclock: Use the --verbose option to see the details of our search for an access method.
rtcwake: /dev/rtc0: unable to find device: No such file or directory

Is this intentional? Is there a work-around to get /dev/rtc0 back?

PS: The host does not complete a reboot with 7.0.14-20, it seems to hang after the shut down part without actually shutting down or rebooting.
I appreciate all the (urgent security) fixes in the new kernel version but this one doesn't really work for me.

EDIT: cat /sys/devices/system/clocksource/clocksource0/available_clocksource gives tsc hpet acpi_pm on both kernel versions.
 
Last edited:
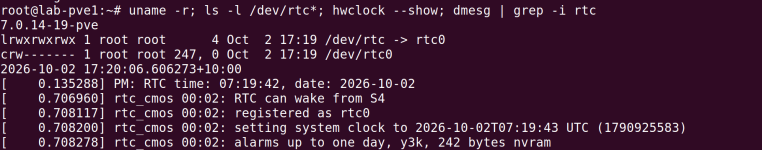
I can reproduce this on a test node (a PVE VM, q35 + OVMF), so it's not just your hardware.

On 7.0.14-19 (and -17) everything is fine. rtc_cmos picks up the clock and hwclock works:

1790926272236.png

On 7.0.14-20 /dev/rtc0 is gone and I get the same hwclock error as you. The RTC driver is still built into the kernel, but it never gets loaded:

1790926287618.png

(Just checking: where your post says "7.0.14-19 breaks this", you mean -20, right?)

From what I can see, the kernel config is basically the same between the two versions, so this looks like a code change in -20. The clock device is still there, but -20 creates it in a different place than before (as a "platform" device instead of a "PnP" device). The RTC driver still looks for it in the old place, doesn't find it, and gives up. So nothing creates /dev/rtc0.

If you want to check it on your box, run this on -20:

Code:
cat /sys/bus/pnp/devices/*/id
ls -l /sys/bus/platform/devices/PNP0B00:00/driver

On mine the first one doesn't list PNP0B00 any more, and the second one says the driver link doesn't exist.

Btw, the clocksource thing in your edit isn't related. That's about the kernel's own timekeeping, not the hardware clock.

For now the easiest fix is to stay on -19:

Code:
proxmox-boot-tool kernel pin 7.0.14-19-pve

Once a fixed kernel comes out, run proxmox-boot-tool kernel unpin.

I couldn't reproduce the reboot hang though, my VM reboots fine on -20. That part might be specific to your hardware. If you can grab the last lines on the console when it hangs, that would help.
 
  • Like
Reactions: leesteken
(Just checking: where your post says "7.0.14-19 breaks this", you mean -20, right?)
Indeed (and fixed), thanks for reproducing the issue.
If you want to check it on your box, run this on -20:

Code:
cat /sys/bus/pnp/devices/*/id
ls -l /sys/bus/platform/devices/PNP0B00:00/driver

On mine the first one doesn't list PNP0B00 any more, and the second one says the driver link doesn't exist.
Maybe later I can test this on -20 but on -19 those give PNP0b00 and there is not such directory.
For now the easiest fix is to stay on -19:
Yes, this was my plan also until something better comes along, as I don't want to run outdated kernel versions for too long. I was mostly wondering whether this was intended as a security fix and whether there was a work-around.

I couldn't reproduce the reboot hang though, my VM reboots fine on -20. That part might be specific to your hardware. If you can grab the last lines on the console when it hangs, that would help.
The last lines on the console are a i915 driver crash because it does not handle unloading very well. This is the same for a successful reboot, so nothing related there. The system logs ends normally:
Code:
Reached target reboot.target - System Reboot.
Shutting down.
Syncing filesystems and block devices.
Sending SIGTERM to remaining processes...
Received SIGTERM from PID 1 (systemd-shutdow).
Journal stopped
I've used kernel parameters to chose a different reboot method in the past on other motherboards. This is usually fixed with a BIOS update. In this case it felt as just another thing with this particular kernel version.
 
I tried 7.0.14-21-pve from pve-test but that behaves the same as -20 except that my AMD GPU no longer shows the Linux boot or shutdown messages, which is very inconvenient when the system hangs with a black screen. Maybe an amdgpu driver or firmware missing as is did not upgrade pve-firmware? Anyway, I'll patiently wait for the next kernel version before testing again.
 
I tried 7.0.14-21-pve from pve-test but that behaves the same as -20
sorry should have written explicit versions here - the version after 7.0.14-21-pve (as this was packaged before the reports)

Maybe an amdgpu driver or firmware missing as is did not upgrade pve-firmware? Anyway, I'll patiently wait for the next kernel version before testing again.
did anything from that boot make it to the journal, that might point to where the error is?

else - upgrading pve-firmware and testing with the next kernel seems like a good way forward!
(fwiw - the igpu of some ryzen systems I run don't have any issues with kernel 7.0.14-21-pve)
 
  • Like
Reactions: leesteken
sorry should have written explicit versions here - the version after 7.0.14-21-pve (as this was packaged before the reports)
No problem, I assumed as much and wanted to try a newer kernel anyway.

did anything from that boot make it to the journal, that might point to where the error is?
The main difference is that one has log lines about rtc0. The crash of the i915 driver when unbound before passthrough is in both; I get the feeling that Linux kernel maintainers don't test for unloading drivers as this happens often with the amdgpu driver as well. There is also the BTRFS warnings about "unable to release extent buffer" on a drive with a VM template and shallow clones during shut down and pvestatd telling me "is not a btrfs file system", which it very much is. But let's not get off-topic.

At lot of log lines happen in parallel but the amdgpu ones appear to be identical. No more (irrelevant) errors and/or warnings in the logs with 7.0.14-21 than 7.0.14-19.
else - upgrading pve-firmware and testing with the next kernel seems like a good way forward!
(fwiw - the igpu of some ryzen systems I run don't have any issues with kernel 7.0.14-21-pve)
It's an RX 9070 GRE, which did not work fully with Linux kernel 6.8 but no known issues with 7.0 (on host and in VMs with passthrough). I'll investigate further (and will try to add more details) when this issue persists in the next kernel update.
 
  • Like
Reactions: Stoiko Ivanov
Kernel version 7.0.14-22-pve brings back access to the hardware clock. :) And boot/shutdown messages are being shown normally.

Unfortunately, my Gigabyte X570S AERO G no longer shuts down or reboots since kernel version 7.0.14-20-pve :(. The shut down/reboot proceeds gracefully (except for unrelated driver unload issues with em288 and i915 and BTRFS warnings) but it does not do the final shut down/reboot. The display ends with systemd-shutdown[1]: Rebooting. and just hangs. The logs look perfectly normal:
Code:
systemd[1]: Reached target shutdown.target - System Shutdown.
systemd[1]: Reached target final.target - Late Shutdown Services.
systemd[1]: systemd-poweroff.service: Deactivated successfully.
systemd[1]: Finished systemd-poweroff.service - System Power Off.
systemd[1]: Reached target poweroff.target - System Power Off.
systemd[1]: Shutting down.
systemd-shutdown[1]: Syncing filesystems and block devices.
systemd-shutdown[1]: Sending SIGTERM to remaining processes...
systemd-journald[943]: Journal stopped

What changed in the power off or reboot sequence of the kernel between -19 and -20? I never had such issues with this motherboard+CPU before. It runs the latest non-beta BIOS.

If this persists then I could start try kernel parameter work-arounds like I once needed with an older motherboard. Or is there something else I could try or investigate?

EDIT: I also updated the pve-firmware but that did not change anything. Reverting back to -19 as I want this system to shut down itself.
EDIT3: There is a reboot= kernel parameter what I can try but is there also one for shut down? Reboot and shutdown do work fine on my nested/virtual PVE setups.
 
Last edited:
The shut down/reboot issue is a bit of a red herring.

The actual issue is that I have a MythTV container that uses a USB DVB-C tuner (over USB/IP). When that container is shut down there is a crash in the em28xx driver with kernel 7.0.14-22-pve. And after that, the system will show the shut down/reboot hanging problem.

Code:
kernel: vmbr2: port 2(fwpr118p0) entered disabled state
kernel: vhci_hcd: connection closed
kernel: vhci_hcd vhci_hcd.0: stop threads
kernel: vhci_hcd vhci_hcd.0: release socket
kernel: vhci_hcd vhci_hcd.0: disconnect device
kernel: usb 9-1: USB disconnect, device number 2
kernel: em28xx 9-1:1.0: Disconnecting em28xx #1
kernel: em28xx 9-1:1.0: Disconnecting em28xx
kernel: em28xx 9-1:1.0: Closing DVB extension
kernel: em28xx 9-1:1.0: Closing input extension
kernel: BUG: kernel NULL pointer dereference, address: 0000000000000000
kernel: #PF: supervisor read access in kernel mode
kernel: #PF: error_code(0x0000) - not-present page
kernel: PGD 0 P4D 0
kernel: Oops: Oops: 0000 [#1] SMP NOPTI
kernel: CPU: 11 UID: 0 PID: 913 Comm: kworker/11:2 Tainted: P           O        7.0.14-22-pve #1 PREEMPT(lazy)
kernel: Tainted: [P]=PROPRIETARY_MODULE, [O]=OOT_MODULE
kernel: Hardware name: Gigabyte Technology Co., Ltd. X570S AERO G/X570S AERO G, BIOS F7 10/28/2025
kernel: Workqueue: usb_hub_wq hub_event
kernel: RIP: 0010:em28xx_close_extension+0x80/0x140 [em28xx]
kernel: Code: 81 fb 50 d2 6a c1 75 cd 49 8b 9c 24 a0 17 00 00 48 85 db 74 4b 48 8b 83 f0 01 00 00 48 8b 93 e8 01 00 00 48 8d bb e8 01 00 00 <48> 3b 38 0f 85 fa 26 00 00 48 3b 7a 08 0f 85 f0 26 00 00 48 89 42
kernel: RSP: 0018:ffffce5c47a3faf8 EFLAGS: 00010286
kernel: RAX: 0000000000000000 RBX: ffff8c7dfa26a000 RCX: 0000000000000000
kernel: RDX: 0000000000000000 RSI: 0000000000000000 RDI: ffff8c7dfa26a1e8
kernel: RBP: ffffce5c47a3fb08 R08: 0000000000000000 R09: 0000000000000000
kernel: R10: 0000000000000000 R11: 0000000000000000 R12: ffff8c7dc36f0000
kernel: R13: ffff8c7de1eabce0 R14: ffffffffc16ad590 R15: ffff8c7de1eabc50
kernel: FS:  0000000000000000(0000) GS:ffff8c8dd0e8a000(0000) knlGS:0000000000000000
kernel: CS:  0010 DS: 0000 ES: 0000 CR0: 0000000080050033
kernel: CR2: 0000000000000000 CR3: 00000001411d0000 CR4: 0000000000f50ef0
kernel: PKRU: 55555554
kernel: Call Trace:
kernel:  <TASK>
kernel:  em28xx_usb_disconnect.cold+0x71/0xbf [em28xx]
kernel:  usb_unbind_interface+0x9b/0x2e0
kernel:  ? srso_alias_return_thunk+0x5/0xfbef5
kernel:  device_remove+0x68/0x80
kernel:  device_release_driver_internal+0x206/0x270
kernel:  ? srso_alias_return_thunk+0x5/0xfbef5
kernel:  device_release_driver+0x12/0x20
kernel:  bus_remove_device+0xfd/0x1c0
kernel:  ? srso_alias_return_thunk+0x5/0xfbef5
kernel:  ? device_remove_attrs+0xb6/0x100
kernel:  device_del+0x160/0x3c0
kernel:  usb_disable_device+0xfa/0x250
kernel:  usb_disconnect+0xe6/0x2e0
kernel:  hub_event+0xe8c/0x1a40
kernel:  ? srso_alias_return_thunk+0x5/0xfbef5
kernel:  ? psi_avgs_work+0x64/0xe0
kernel:  process_one_work+0x1a9/0x3c0
kernel:  worker_thread+0x1b8/0x360
kernel:  ? srso_alias_return_thunk+0x5/0xfbef5
kernel:  ? __pfx_worker_thread+0x10/0x10
kernel:  kthread+0xf7/0x130
kernel:  ? __pfx_kthread+0x10/0x10
kernel:  ret_from_fork+0x2da/0x3a0
kernel:  ? __pfx_kthread+0x10/0x10
kernel:  ret_from_fork_asm+0x1a/0x30
kernel:  </TASK>
kernel: Modules linked in: veth rc_hauppauge em28xx_rc si2157 si2168 i2c_mux ebt_arp ebtable_filter ebtables ip6table_raw ip6t_REJECT nf_reject_ipv6 ip6table_filter ip6_tables iptable_raw xt_NFLOG xt_limit xt_mac xt_connmark ipt_REJECT nf_reject_ipv4 xt_mark xt_set xt_physdev xt_addrtype xt_co>
kernel:  snd_timer pcspkr k10temp cfg80211 rc_core i2c_algo_bit snd libarc4 video soundcore joydev input_leds mac_hid sch_fq_codel vhost_net vhost vhost_iotlb tap ledtrig_oneshot ledtrig_timer ledtrig_heartbeat it87 hwmon_vid em28xx_dvb em28xx tveeprom dvb_core videodev mc vhci_hcd usbip_core >
kernel: CR2: 0000000000000000
kernel: ---[ end trace 0000000000000000 ]---
kernel: RIP: 0010:em28xx_close_extension+0x80/0x140 [em28xx]
kernel: Code: 81 fb 50 d2 6a c1 75 cd 49 8b 9c 24 a0 17 00 00 48 85 db 74 4b 48 8b 83 f0 01 00 00 48 8b 93 e8 01 00 00 48 8d bb e8 01 00 00 <48> 3b 38 0f 85 fa 26 00 00 48 3b 7a 08 0f 85 f0 26 00 00 48 89 42
kernel: RSP: 0018:ffffce5c47a3faf8 EFLAGS: 00010286
kernel: RAX: 0000000000000000 RBX: ffff8c7dfa26a000 RCX: 0000000000000000
kernel: RDX: 0000000000000000 RSI: 0000000000000000 RDI: ffff8c7dfa26a1e8
kernel: RBP: ffffce5c47a3fb08 R08: 0000000000000000 R09: 0000000000000000
kernel: R10: 0000000000000000 R11: 0000000000000000 R12: ffff8c7dc36f0000
kernel: R13: ffff8c7de1eabce0 R14: ffffffffc16ad590 R15: ffff8c7de1eabc50
kernel: FS:  0000000000000000(0000) GS:ffff8c8dd0e8a000(0000) knlGS:0000000000000000
kernel: CS:  0010 DS: 0000 ES: 0000 CR0: 0000000080050033
kernel: CR2: 0000000000000000 CR3: 0000001f7ea3e000 CR4: 0000000000f50ef0
kernel: PKRU: 55555554

Restarting the container 118 works fine and I don't see any other issues. Just the Proxmox host won't shut down/reboot anymore. This em28xx crash did not happen on -19 and started from -20 onward.

EDIT: Probably be the same as https://forum.proxmox.com/threads/c...ssed-through-em28xx-tuner-on-vm-start.186799/ except it breaks the shut down/reboot for me. And this is not the first time this happened: https://forum.proxmox.com/threads/a...-passthrough-locks-system.103318/#post-444771 . Could it be related to the fix for CVE-2026-89891?
 
Last edited: