zeus86's latest activity
-
ZQuick follow-up for anyone hitting this: Hetzner support answered my ticket, and it confirms the issue is on their side. In short: - their Object Storage clusters have grown fast, so they are migrating buckets between clusters and applying...
-
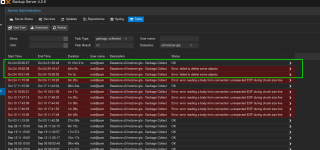
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.meanwhile the second instance finally also went through. as it can be seen from the screenshot, this instance had failure for longer in the past in total. once in a while a run finished fine (after putting in to a timeslot where nothing else was...
-
-
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.One of my instances already finished. it actually took 3 attempts, because of failed to delete some objects (without further details) in step 2. However, I think the api-command to actually delete the object went through just fine anyways...
-
-
ZSame issue here, and I think I found what fixed it in my case. Setup: PBS 4.2.8 (kernel 7.0.14-25-pve), S3 datastore on Hetzner Object Storage (hel1), vhost-style addressing, provider quirk `skip-if-none-match-header` already set. Syncs to the...
-
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.I'll test that, because my jobs are meanwhile failing since almost 2 weeks consecutively. GC is already currently running. I'll report back for my 2 instances, if this solved the problem. If this is confirmed to work, this might be worth...
-
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.after some runs did complete meanwhile, today i had another error. as requested, here the full log (with redacted hostnames).
-
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.short update: i manually remove those backups from s3 where the verification fails (were some of the oldest anyways), and additionally temporarily adjusted the retention time, so that another 2 of the oldest backups (each) were removed. however...
-
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.currently i am running 4.2.0 still. full trail: proxmox-backup 4.2.0 running kernel: 7.0.0-3-pve proxmox-backup-server 4.2.5-1 running version: 4.2.0 proxmox-kernel-helper 9.2.0...
-
Zzeus86 replied to the thread S3 Hetzner failures with Gargbage collection.did anyone found a real root cause for this? i currently have the exact same problem also on a hetzner s3 bucket, and i suspect some backups that did failed verification are the curlpit. for some reason, 3 older backups actually failed...