ThomasA's latest activity
-
TThomasA reacted to hidigoudi's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with
 Like.
The original issue in this post has been identified and fixed in kernel 7.0.14-19. More info here: https://bugzilla.proxmox.com/show_bug.cgi?id=7734
-
TThomasA replied to the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown.Did I say "no issues since the kernel patching"? Seems like I stay corrected. dmesg -T this morning shows: [Tue Sep 15 23:06:58 2026] kworker/u48:17: page allocation failure: order:9, mode:0x40c40(GFP_NOFS|__GFP_COMP)...
-
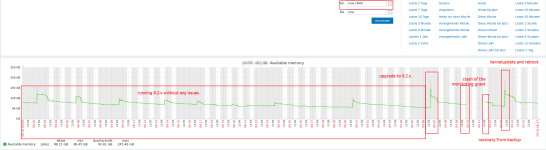
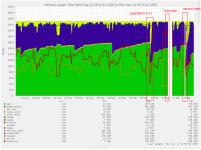
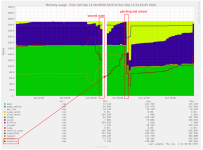
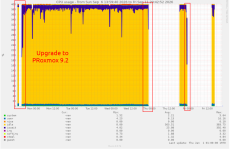
TThomasA replied to the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown.Hi @fiona, thanks for your swift reply. Being not sure which logs from the system describe the memory situation over time I'm just sharing charts from the Zabbix and Munin monitoring over one month. I've patched and rebooted the node into to...
-
-
TThomasA reacted to Corecounter's post in the thread Wo finde ich Changelogs von Proxmox PVE? with Like.
Ich hab noch für mich zwei bessere Lösungen gefunden. Und ja, Augen auf bei der Administration. ;) 1. Changelog für jedes Paket steht beim Update in der Update-GUI. Ist aber nach dem Update leider weg. :rolleyes: (Hatte ich leider völlig...
-
TThomasA replied to the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown.Had another died guest today. Luckily no disk failure this time. But a died guest is not too good either. This crash here occurred during a vzdump backup. The two other disk failures too. The chain of events were commonly: * vzdump starts...
-
TThomasA reacted to static302's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with Like.
We hit the same signature across VMs with different guest kernels and across different nodes of 1 cluster: - Ubuntu 22.04.5, kernel 5.15.0-181 (XFS data disks fail; ext4 root survives) - RHEL 8.10, kernel 4.18.0-553 (XFS) Host: - Proxmox VE...
-
TThomasA replied to the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown.Upgraded to proxmox 9.2.10 on Sunday September the 6th. Have had two downtimes of a host because of that since. Both downtimes occurred during the Proxmox Backup of some other machines which places an extra burden on the physical disks. And in...
-
-
TThomasA reacted to hidigoudi's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with Like.
By the way, I also reproduced the issue on AlmaLinux 10.1 (kernel 6.12.0-124.52.1.el10_1.x86_64) with this command : fio --name=stress-hdd --ioengine=libaio --iodepth=8 --rw=randwrite \ --bs=4k --direct=1 --fdatasync=8 --size=20G --numjobs=4...
-
TThomasA reacted to meyergru's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with Like.
I now have seen this behavior, too, but with ZFS on the PVE host and both ext4 and ZFS on the VM guests. The machine is equipped with SSD-only, 6 NVME, 2 SATA. All of them are in three ZFS mirror pools (one with 2x NVME, one with 4 and the last...
-
TThomasA reacted to hidigoudi's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with Like.
The problem is also triggered on last kernel 7.0.12-1-pve. [root@patchmon ~]# fio --name=stress-hdd --ioengine=libaio --iodepth=8 --rw=randwrite --bs=4k --direct=1 --fdatasync=8 --size=20G --numjobs=8 --runtime=1800 --time_based...
-
TThomasA reacted to hidigoudi's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with Like.
Some news : I was able to reboot one of the both Proxmox host on Kernel 6.17.13-13-pve and retry the same process / same stress write test (30 minutes of stress). I confirm that there is no issue on this kernel version. So it seems to be a...
-
TThomasA reacted to hidigoudi's post in the thread [SOLVED] io_uring on kernel 7.0.6-2-pve (PVE 9.2.3): guest disk I/O errors (EIO) + filesystem XFS shutdown with Like.
I just find a way to reproduce the issue on the guest : root@zabbix :~$ fio --name=stress-write --ioengine=libaio --iodepth=64 --rw=randwrite \ --bs=4k --direct=1 --size=20G --numjobs=8 --runtime=600 \ --time_based --ramp_time=30...